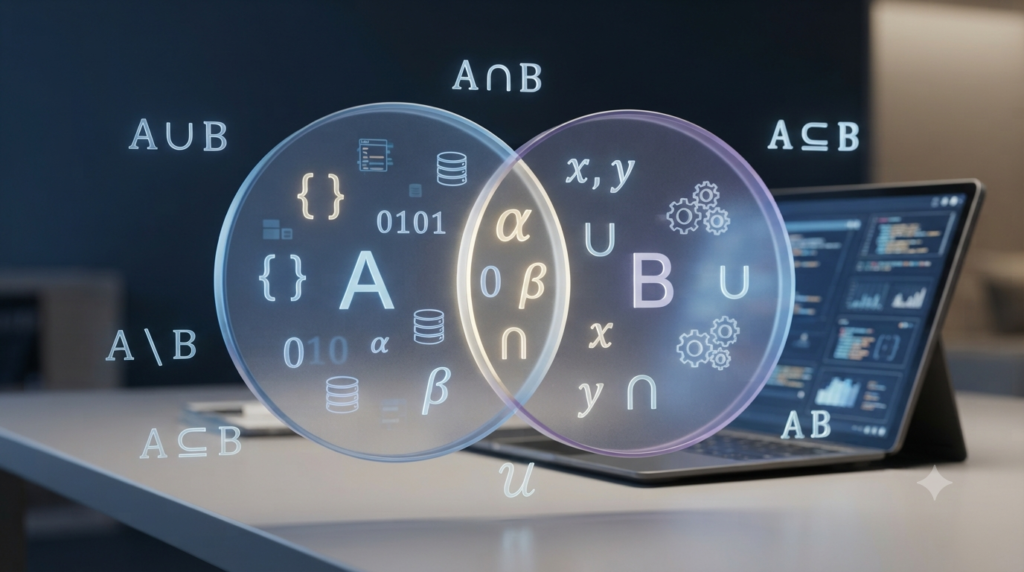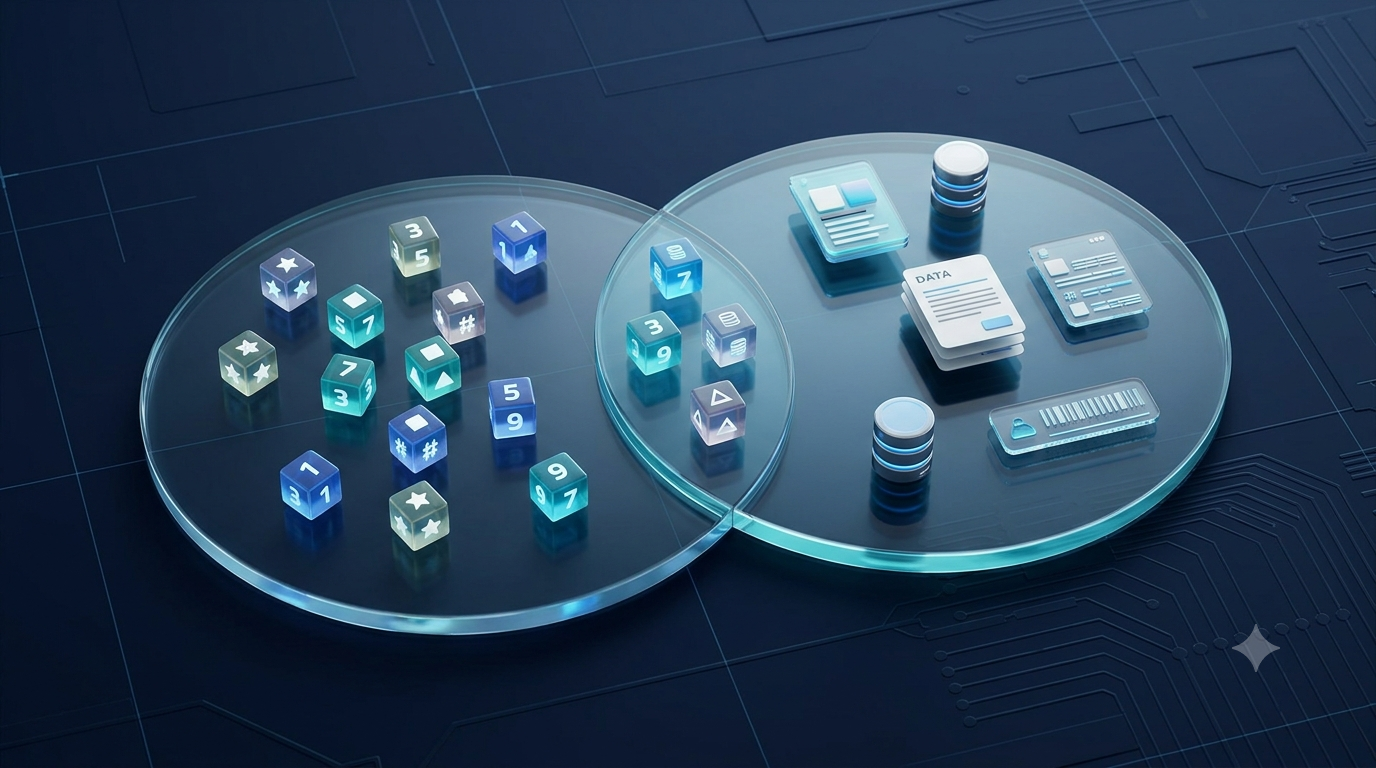
Computer science involves working with different types of data, including numbers, words, usernames, website addresses, and records. Organizing this information properly helps computers process it efficiently and accurately. One important mathematical concept used for this purpose is a set. A set is a collection of distinct elements that are treated as a single group. Sets are useful when we need to store unique values, identify common elements, remove duplicates, and compare different collections of information.
Sets are closely connected to mathematics, programming, databases, cybersecurity, and data analysis. For example, a website may use a set to keep track of unique visitors, while a programming application may use sets to identify common interests between users. Understanding how sets work makes it easier to solve many everyday computing problems. In this article, we will learn what sets are, how they represent collections of data, which operations can be performed on them, and why they are useful in computer science.
What Is a Set in Computer Science?
A set is an unordered collection of unique elements. Each element appears only once, even if the same value is provided multiple times.
For example, consider the following collection of numbers:
Text block:
A = {2, 4, 6, 8, 10}Here, A is a set containing five elements. The elements are 2, 4, 6, 8, and 10.
Now consider a collection containing repeated values:
Text block:
B = {2, 4, 4, 6, 6, 8}As a mathematical set, B is equivalent to:
Text block:
B = {2, 4, 6, 8}The repeated values do not create additional elements because sets contain only distinct values.
In computer science, sets can contain different types of information depending on the programming language and application. A set might store integers, text strings, identifiers, or other values.
For example:
Text block:
Languages = {"Python", "Java", "C++"}This set represents three programming languages. It provides a convenient way to work with the collection without worrying about duplicate entries.
Why Are Sets Important for Representing Data?
Sets provide a simple way to organize information when uniqueness and membership matter. Instead of treating every value as a separate item in a long list, a set allows a program to manage distinct values as one collection.
Several characteristics make sets especially useful.
1. Sets Store Unique Elements
The most important property of a set is that it does not contain duplicate elements.
Imagine that an online learning platform records the usernames of people who visit a particular page. A user might visit the same page several times during the day. If the system stores every visit without removing repeated usernames, it may count one person multiple times.
A set can represent the unique visitors.
Text block:
Visitors = {"Amit", "Priya", "Rahul", "Amit", "Priya"}The resulting set contains only:
Text block:
Visitors = {"Amit", "Priya", "Rahul"}This makes it easier to calculate the number of distinct visitors.
Sets are therefore useful for managing unique usernames, product IDs, email addresses, student identifiers, and other values that should not be counted repeatedly.
2. Sets Represent Unordered Collections
In a mathematical set, the order of elements does not matter.
For example:
Text block:
A = {1, 2, 3}
Both sets contain exactly the same elements, so they are equal.
This property is useful when the purpose of a collection is to identify which values are present rather than the order in which they appear.
For instance, a set of permissions might contain the permissions to read, write, and edit a file. The order of these permissions is generally irrelevant when determining which actions are allowed.
However, sets are not suitable when the sequence of elements must be preserved. In such cases, lists, arrays, or other ordered data structures may be more appropriate.
3. Sets Support Efficient Membership Testing
Membership testing determines whether a particular value belongs to a collection.
For example, a computer program may need to check whether a username is already registered or whether a product ID is included in a particular category.
In mathematical notation, membership can be represented using the symbol ∈.
Text block:
A = {10, 20, 30, 40}
The first statement means that 20 belongs to A. The second means that 50 does not belong to A.
Programming languages commonly provide operations that check whether a value exists in a set. Many set implementations support average-case membership checks in constant time, O(1), using hash tables. The actual performance depends on the implementation and the data involved.
This can make sets more convenient than searching through a long list when a program repeatedly needs to check whether specific values exist.
Basic Set Operations Used in Computer Science
Sets become even more useful when we perform operations that compare or combine collections. Four important operations are union, intersection, difference, and symmetric difference.
1. Union of Sets
The union of two sets contains every element that appears in either set, without repeating duplicates.
The union operation is represented by the symbol ∪.
Text block:
A = {1, 2, 3}
In this example, the element 3 appears in both sets but occurs only once in the result.
In computer science, union can be used to combine collections of unique values. For example, an online store might combine the product categories viewed by two users to determine all categories viewed by either person.
Union is also useful when combining search results, merging groups of identifiers, and collecting unique records from multiple sources.
2. Intersection of Sets
The intersection of two sets contains only the elements that appear in both sets. It is represented by the symbol ∩.
Text block:
A = {1, 2, 3, 4}
The elements 3 and 4 are common to both sets.
Suppose one set represents users who enjoy mathematics and another represents users who enjoy computer science. Their intersection identifies users who enjoy both subjects.
Intersection is widely useful for filtering information, comparing user interests, finding common permissions, and retrieving records that satisfy multiple membership conditions.
3. Difference Between Sets
The difference between two sets contains the elements that belong to the first set but not to the second.
It is represented by the symbol − or sometimes by a backslash, depending on the notation used.
Text block:
A = {1, 2, 3, 4}
The elements 1 and 2 belong to A but not to B.
A practical example is identifying registered users who have not completed a particular activity. One set could contain all registered users, while another contains users who have completed the activity. Subtracting the second set from the first identifies those who have not completed it.
Set difference is useful for identifying missing entries, filtering unwanted values, comparing permissions, and determining which records are present in one collection but absent from another.
4. Symmetric Difference
The symmetric difference contains elements that belong to either of two sets, but not to both.
Text block:
A = {1, 2, 3}
The shared element 3 is excluded because it belongs to both sets.
This operation can help identify differences between two groups, compare changing collections, or determine which items appear in only one of two datasets.
How Sets Are Used in Programming Languages
Many programming languages provide built-in set data structures or libraries that make set operations easier to perform.
Python, for example, includes a built-in set type. A programmer can create a set, add elements, remove elements, and compare collections using straightforward syntax.
Example of Creating and Using a Set in Python
Text block:
numbers = {10, 20, 30, 20, 40}
The first line creates a set containing several numbers. Because sets store unique elements, the repeated value 20 is represented only once.
The membership expression checks whether 20 belongs to the set. The add() method inserts 50, while discard() removes 10 if it exists.
The order in which elements appear when a set is displayed is not guaranteed. Therefore, a programmer should not depend on a particular output order.
Example of Combining Two Sets
Text block:
science_students = {"Amit", "Priya", "Rahul"}
The & operator calculates the intersection, identifying students who belong to both groups. The | operator calculates the union, combining all unique students.
These operations demonstrate how a small amount of code can solve problems that would otherwise require manually comparing many entries.
Other languages, including Java and C++, also provide set-related data structures through their standard libraries. Their exact behavior and performance characteristics depend on the implementation being used.
Applications of Sets in Databases
Databases store information about users, products, transactions, customers, and many other entities. Sets provide a useful mathematical model for understanding how records can be selected, combined, and compared.
For example, imagine a database containing customers who purchased different products.
One collection may represent customers who purchased laptops, while another represents customers who purchased smartphones. The intersection of these collections identifies customers who purchased both types of products.
Similarly, the union identifies customers who purchased at least one of the two product types.
Database systems often use set-based ideas when processing queries. SQL also supports operations such as UNION, INTERSECT, and EXCEPT in systems that implement these operations. These commands combine or compare query results according to their defined rules.
For example:
Text block:
SELECT customer_id FROM LaptopBuyers
This query returns customer IDs appearing in both query results, assuming the database system supports INTERSECT.
A set-based approach helps developers express data retrieval tasks clearly. However, real database tables can contain duplicate rows unless constraints or query operations prevent them, so a table should not automatically be treated as a mathematical set in every situation.
Sets in Data Analysis
Data analysis often requires comparing groups, removing repeated observations, and identifying relationships between datasets. Sets are valuable for these tasks.
Consider a survey asking people which subjects they enjoy. The responses may contain repeated subjects because many participants select the same option.
A set can represent the distinct subjects mentioned in the survey.
Text block:
Subjects = {
This representation helps identify the different subjects included in the responses.
Sets can also help compare datasets collected at different times. For example, an analyst might compare customer IDs from January with customer IDs from February to identify returning customers and customers who appeared in only one month.
In data cleaning, sets can be used to identify distinct categories, check whether expected values are present, and compare actual values with an approved list of values.
For very large datasets, specialized database operations, distributed processing systems, or other data structures may be more appropriate. Nevertheless, the underlying principles of set membership and comparison remain important.
Sets in Cybersecurity and Access Control
Cybersecurity systems frequently need to determine which users have permission to access particular resources. Sets offer a clear way to represent collections of permissions.
For example:
Text block:
UserPermissions = {"read", "write"}
The first set represents two permissions, while the second contains three.
A program can compare these sets to determine whether a user has a required permission. It can also calculate the difference between an administrator’s permissions and a regular user’s permissions to identify additional privileges.
Sets are also useful for managing unique blocked IP addresses, approved domains, suspicious identifiers, and known indicators of compromise.
For example, a security system may maintain a set of blocked IP addresses and check whether a connection’s source address belongs to that collection.
However, using a set alone does not make a system secure. Access control must also include correct authentication, authorization rules, appropriate validation, and careful handling of data.
Sets and Graphs in Computer Science
Graphs are mathematical structures used to represent relationships between objects. They consist of vertices, also called nodes, and edges that connect them.
Sets provide a natural way to represent the components of a graph.
For example, a simple graph may contain the following vertices:
Text block:
V = {A, B, C, D}Here, V is the set of vertices.
Its edges can also be represented as a set of connections:
Text block:
E = {(A, B), (A, C), (B, D)}Each ordered pair describes a connection according to the chosen graph representation. For an undirected graph, the pair represents a connection without a direction.
Graphs are used in social networks, road maps, computer networks, recommendation systems, and search algorithms. Representing vertices and edges as sets helps computer scientists reason about which objects exist and how they are connected.
For example, a social network may represent users as vertices and friendships as edges. Algorithms can then analyze connections to identify shared friends, communities, or possible paths between users.
Sets Versus Lists and Arrays
Although sets are useful, they are not the best choice for every collection of data. Lists and arrays provide different capabilities.
A list or array generally preserves element order and may allow duplicate values. A set focuses on unique membership and commonly ignores element order.
Consider the following example:
Text block:
List = [5, 3, 5, 2]
The list preserves the repeated value 5 and its position. The set contains only the distinct values.
The choice depends on the task.
Use a set when you need to remove duplicates, test membership, compare groups, or manage unique identifiers.
Use a list or array when order matters, repeated values must be preserved, or elements need to be accessed by position.
A program may also use both structures together. For example, a list can preserve the order of website visits, while a set tracks which users have already been counted.
Advantages and Limitations of Sets
Sets offer several important advantages in computer science.
First, they automatically maintain uniqueness according to the equality rules of the set implementation. Second, they provide convenient operations for comparing and combining collections. Third, many implementations offer fast membership testing, making them valuable for large collections of distinct values. Finally, set notation provides a clear mathematical language for describing data relationships.
However, sets also have limitations.
They generally do not preserve the meaningful sequence of elements. They may not support duplicate values, and some implementations require elements to be immutable or hashable. In addition, sets can consume extra memory to maintain their internal structure.
Performance also depends on the implementation. Hash-based sets often provide average-case constant-time membership checks, whereas tree-based sets commonly provide logarithmic-time operations. Neither guarantee applies universally to every set implementation.
Understanding these limitations helps programmers select the right data structure for a particular problem.
Conclusion
Sets are an important mathematical and computational tool for representing collections of distinct data. Their ability to eliminate duplicates, test membership, and perform operations such as union, intersection, and difference makes them useful across many areas of computer science.
From programming and databases to data analysis, cybersecurity, and graph theory, sets help organize information and reveal relationships between collections. They also make many algorithms easier to express and understand.
Although sets are not ideal when element order or duplicates must be preserved, they are highly effective when uniqueness and membership are the main concerns. By understanding their properties, operations, advantages, and limitations, programmers can choose suitable data structures and develop clearer, more efficient solutions to real-world computing problems.
FAQs
1. What is a set in computer science?
A set in computer science is a collection of distinct elements treated as a single group. These elements may include numbers, strings, usernames, identifiers, or other supported data values. The main characteristic of a set is that duplicate elements are not stored as separate members. For example, the set {2, 4, 4, 6} represents the distinct values {2, 4, 6}. Sets are useful for organizing data, checking whether an element exists, removing duplicates, and comparing collections. They are widely used in programming, databases, data analysis, cybersecurity, and mathematical problem-solving.
2. Why are sets useful for representing collections of data?
Sets are useful because they provide a simple way to represent unique values and perform operations on collections. They automatically eliminate duplicate elements according to their equality rules, making them suitable for managing unique usernames, product identifiers, and categories. Sets also support operations such as union, intersection, and difference, which help programmers compare different collections efficiently. Many implementations provide fast membership testing, allowing programs to check whether a particular value exists. These features make sets valuable in applications involving data cleaning, database queries, access control, and information retrieval, where uniqueness and membership are important.
3. How do sets remove duplicate values from data?
Sets remove duplicates by maintaining only one occurrence of each distinct element. When repeated values are added to a set, additional occurrences do not create new members. For example, the collection {10, 20, 20, 30, 30} becomes {10, 20, 30} when represented as a mathematical set. In Python, programmers can convert a list into a set to obtain its unique values. However, this conversion does not guarantee preservation of the original order. Sets are particularly useful for cleaning repeated identifiers, collecting unique survey responses, and identifying distinct visitors in web applications.
4. What are the main operations performed on sets?
The four commonly discussed set operations are union, intersection, difference, and symmetric difference. Union combines all distinct elements from two sets. Intersection identifies elements shared by both sets. Difference returns elements present in one set but absent from another. Symmetric difference identifies elements belonging to either set but not both. For example, if A is {1, 2, 3} and B is {3, 4, 5}, their intersection is {3}, while their union is {1, 2, 3, 4, 5}. These operations help programmers compare datasets, filter information, and identify relationships between collections.
5. How are sets used in Python programming?
Python provides a built-in set data type for storing unique, hashable elements. Programmers can create sets using curly braces or the set() constructor. Common operations include adding elements with add(), removing elements with discard(), checking membership with the in operator, and combining collections with operators such as | and &. For example, numbers = {1, 2, 2, 3} creates a set containing the distinct values 1, 2, and 3. Python sets are useful for removing duplicates, checking whether values exist, comparing groups, and simplifying data-processing tasks.
6. What is the difference between a set and a list?
A set stores distinct elements without treating their positions as meaningful, whereas a list generally preserves element order and allows duplicate values. For example, the list [2, 4, 2, 6] contains four entries, while the set {2, 4, 6} contains three distinct elements. Lists are suitable when sequence, position, or repeated values matter. Sets are preferable when uniqueness and membership testing are the main concerns. In many programming languages, sets also provide efficient membership checks. Choosing between them depends on the application’s requirements, and programmers sometimes use both structures together.
7. How are sets useful in database management?
Sets are useful in database management because they help explain how records can be combined, compared, and filtered. For example, a business may maintain collections of customers who purchased laptops and customers who purchased smartphones. The intersection identifies customers who purchased both products, while the union identifies customers who purchased either product. SQL provides operations such as UNION, INTERSECT, and EXCEPT in database systems that support them. These operations help retrieve and compare query results. However, database tables can contain duplicate rows, so database results do not always behave exactly like mathematical sets.
8. How do sets improve data analysis?
Sets help data analysts identify unique values, compare datasets, and discover relationships between groups. For example, an analyst can use sets to identify distinct product categories, remove repeated customer identifiers, or compare website visitors across different months. The intersection of two sets can reveal returning customers, while the difference can identify customers appearing in one period but not another. Sets are also useful for validating data against approved lists of values. These capabilities simplify several data-cleaning and comparison tasks. For extremely large datasets, specialized tools may be necessary, but set operations remain an important foundation of data analysis.
9. How are sets used in cybersecurity?
Sets can represent collections of security-related information, including user permissions, blocked IP addresses, approved domains, and suspicious identifiers. For example, a security application can maintain a set of blocked IP addresses and check whether an incoming connection’s address belongs to that collection. Sets can also help compare user permissions with the permissions required for a particular action. Their membership-testing capabilities make them useful for these checks. However, a set alone does not provide complete security. Reliable cybersecurity also requires authentication, authorization, appropriate validation, monitoring, and careful implementation of access-control policies.
10. What are the limitations of sets in computer science?
Sets have several limitations that programmers should consider. They generally do not preserve a meaningful element order, and they do not store duplicate values as separate members. Therefore, they are unsuitable when an application must maintain a sequence or record repeated entries. Some implementations also restrict the types of elements that can be stored. Sets may require additional memory for their internal organization, and their performance depends on the implementation. Hash-based sets often provide average-case constant-time membership testing, while tree-based sets commonly provide logarithmic-time operations. Programmers should choose sets when their advantages match the requirements of the task.