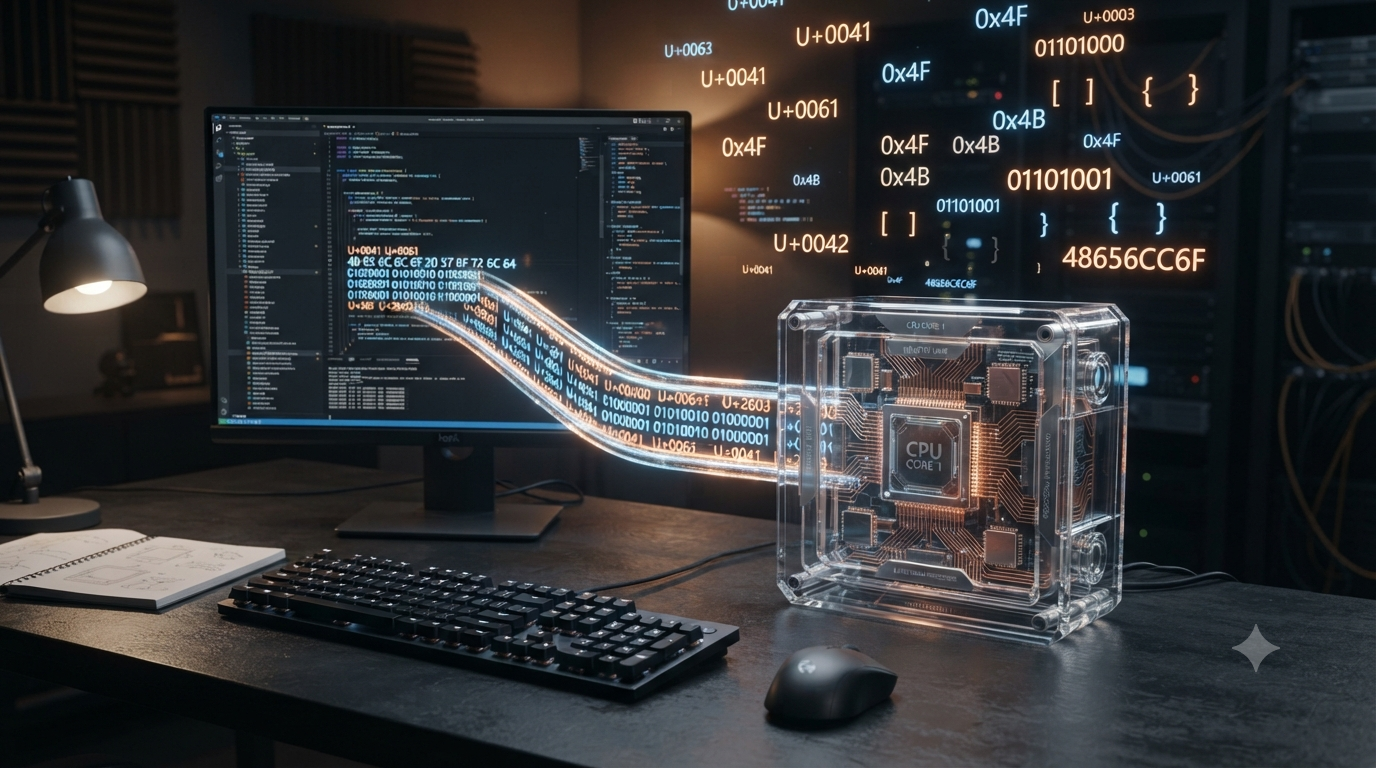
When computers process text, they do not directly understand letters, numbers, punctuation marks, or symbols in the same way humans do. A computer ultimately works with numerical data. Therefore, every character in a piece of text must be represented by a number so that it can be stored, processed, transmitted, and displayed correctly. Character encoding provides the rules that connect human-readable characters with numerical values.
One important concept in character encoding is the code point. A code point is a numerical value assigned to a character in a character set such as Unicode. Understanding code points makes it easier to see how computers represent text and how simple calculations can be performed using character values.
Character encoding is used everywhere, from websites and mobile applications to operating systems, databases, programming languages, and digital documents. This article explains the basic ideas behind character encoding, code points, common encoding systems, and simple code point calculations.
What Is Character Encoding?
Character encoding is a system of rules used to represent characters as numerical data that computers can store and process.
For example, the English capital letter A is assigned a numerical value in several character systems. In ASCII, the value of A is 65. The lowercase letter a has the value 97.
This means that when a computer receives the character A in an ASCII-compatible context, it can represent it using the number 65.
The basic process can be understood as:
Character → numerical value → binary data
For example:
A → 65 → 01000001
The exact binary representation depends on the encoding being used. Character encoding therefore acts as a bridge between human-readable text and computer-readable data.
What Is a Character Set?
A character set is a collection of characters together with numerical identifiers assigned to those characters.
A character set may contain letters, digits, punctuation marks, symbols, and characters from different writing systems.
For example, a simple character set might contain:
A
B
C
a
b
c
0
1
2
Each character can be associated with a numerical value.
It is important to distinguish a character set from an encoding. A character set defines which characters exist and their associated values, while an encoding defines how those values are represented as bytes or other units for storage and transmission.
Unicode is a major universal character system designed to provide identifiers for characters from many writing systems.
What Is a Code Point?
A code point is a numerical value assigned to a character in a character encoding or character set, particularly in Unicode.
Unicode assigns code points to characters using hexadecimal notation. Unicode code points are commonly written in the form:
U+XXXX
For example:
A → U+0041
B → U+0042
a → U+0061
0 → U+0030
The U+ indicates that the number is a Unicode code point, while the following hexadecimal digits represent its numerical value.
For example:
U+0041
Here, 0041 is hexadecimal. Converting it to decimal gives:
0x41 = 65
Therefore, the Unicode code point for A has the decimal value 65.
Why Are Code Points Important?
Code points provide a consistent numerical identity for characters.
Suppose a program needs to determine whether two characters are different or whether one character comes before another in a particular character sequence. Numerical values can make such operations easier.
Code points are also useful when:
Processing text programmatically
Comparing characters
Converting between character representations
Understanding Unicode
Debugging text encoding problems
Studying programming and computer science
Performing simple character calculations
For example, the code points for uppercase English letters are consecutive:
This makes some basic calculations possible.
ASCII and Character Codes
Before Unicode became widely used, ASCII was one of the most important character encoding standards for English text.
ASCII originally defines 128 characters, numbered from 0 to 127. These include uppercase and lowercase English letters, digits, punctuation marks, and control characters.
Some common ASCII values are:
| Character | Decimal value | Hexadecimal |
|---|---|---|
| A | 65 | 41 |
| B | 66 | 42 |
| C | 67 | 43 |
| Z | 90 | 5A |
| a | 97 | 61 |
| b | 98 | 62 |
| z | 122 | 7A |
| 0 | 48 | 30 |
| 1 | 49 | 31 |
| 9 | 57 | 39 |
ASCII is useful for learning basic character calculations because many common English characters have simple, sequential numerical values.
Unicode and Code Points
Unicode was created to provide a much broader system for representing text from languages and writing systems around the world.
Unlike the original ASCII system, Unicode includes characters from many languages, mathematical symbols, technical symbols, punctuation systems, and emoji.
Examples include:
A → U+0041
é → U+00E9
Ω → U+03A9
中 → U+4E2D
Unicode code points can range from:
U+0000 to U+10FFFF
However, not every possible code point represents an assigned character.
Unicode itself is not the same thing as UTF-8, UTF-16, or UTF-32. Unicode defines code points, while UTF encodings define ways of representing those code points as computer data.
Character Encoding vs Code Point
These two concepts are related but not identical.
A code point identifies a character numerically.
An encoding determines how that numerical value is represented in stored or transmitted data.
For example, the character A has the Unicode code point:
U+0041
In UTF-8, this character is represented using one byte:
41 hexadecimal
In decimal, that byte is:
65
Therefore:
For characters outside the basic ASCII range, UTF-8 may require multiple bytes.
What Is UTF-8?
UTF-8 is one of the most widely used Unicode encoding formats.
It uses between 1 and 4 bytes to represent a Unicode code point.
Characters in the ASCII range use one byte in UTF-8. Many other characters require two, three, or four bytes.
For example:
A → U+0041 → 1 UTF-8 byte
A character such as € has the Unicode code point:
U+20AC
Its UTF-8 representation uses three bytes.
This distinction is important because the number of bytes used to store a character is not always the same as its code point value.
Basic Code Point Calculations
Simple code point calculations are often based on converting between decimal and hexadecimal values or finding the numerical difference between characters.
For example, consider:
A = U+0041
The hexadecimal value 41 can be converted into decimal:
4 × 16 + 1 = 65
Therefore:
U+0041 = decimal 65
Similarly:
B = U+0042
So:
4 × 16 + 2 = 66
Therefore:
B = 66
Because A and B have consecutive code points:
66 − 65 = 1
The difference between their code points is 1.
Calculating the Code Point of a Letter
For the English uppercase alphabet, the code points are consecutive.
The code point of A is:
65
Therefore, the code point of another uppercase letter can be calculated using its position in the alphabet.
For example, D is the fourth letter.
The calculation is:
65 + (4 − 1) = 68
Therefore:
D = 68
The same principle works for lowercase letters.
The code point of lowercase a is:
97
The code point of lowercase d is:
97 + (4 − 1) = 100
Therefore:
d = 100
This calculation works because the English alphabet characters occupy consecutive code point values in Unicode.
Finding the Difference Between Characters
The numerical difference between code points can also be calculated.
Consider uppercase A and uppercase F:
Therefore:
70 − 65 = 5
The code point difference is 5.
This does not mean there are exactly five characters between A and F. Rather, the numerical difference between their code points is five.
For example:
The sequence demonstrates why the calculation works.
Uppercase and Lowercase Code Point Calculations
A useful observation in the English alphabet is the difference between corresponding uppercase and lowercase letters.
For example:
Therefore:
97 − 65 = 32
The same difference applies to corresponding letters such as B and b:
Again:
98 − 66 = 32
Therefore, for English letters in these ranges:
lowercase code point = uppercase code point + 32
For example, if the uppercase letter is C:
C = 67
Then:
67 + 32 = 99
So:
c = 99
This relationship is useful in basic programming exercises involving character conversion.
Decimal and Hexadecimal Code Point Calculations
Unicode code points are commonly written in hexadecimal, so knowing how to convert between decimal and hexadecimal is helpful.
Consider the decimal value:
65
To convert 65 to hexadecimal:
65 ÷ 16 gives a quotient of 4 and a remainder of 1.
Therefore:
65 = 0x41
So:
65 decimal = U+0041
Another example is decimal 97:
97 ÷ 16 = 6 remainder 1
Therefore:
97 = 0x61
So:
97 decimal = U+0061
This corresponds to lowercase a.
Code Point Calculations Are Not Byte Calculations
One of the most important points to understand is that a code point and a byte representation are not necessarily the same thing.
For example:
A → U+0041
The code point has the hexadecimal value 0041, but in UTF-8, A requires only one byte:
41
For a character outside the ASCII range, the difference becomes more noticeable.
A Unicode character may have one code point but require multiple bytes in UTF-8.
Therefore, it is incorrect to assume that:
one character = one byte
This is true for many ASCII characters in UTF-8, but not for all Unicode characters.
Code Point vs Character Count
Another important distinction is between the number of characters in text and the number of bytes used to store that text.
For example, the word:
ABC
contains three characters.
Each character is represented by one ASCII-compatible UTF-8 byte, so the text requires three bytes.
However, text containing characters outside the ASCII range may require more bytes per character.
This means that:
Character count ≠ byte count
A program working with text must therefore understand whether it is counting characters, Unicode code points, or encoded bytes.
Common Mistakes in Character Encoding
Several misunderstandings are common when learning character encoding.
Mistaking Code Points for Encoded Bytes
A Unicode code point identifies a character, while an encoding such as UTF-8 determines how that character is stored as bytes.
They are related, but they are not interchangeable concepts.
Assuming Every Character Uses One Byte
ASCII characters generally use one byte in UTF-8, but many Unicode characters require multiple bytes.
Therefore, character count and byte count can differ.
Confusing Decimal and Hexadecimal
Unicode code points are normally displayed in hexadecimal notation.
For example:
U+0041
does not mean that the decimal value is 41. The 41 is hexadecimal.
It represents:
4 × 16 + 1 = 65
Assuming All Code Points Represent Characters
Unicode has a large code point range, but not every possible numerical value is assigned to a character.
Therefore, a numerical value within the Unicode range does not automatically mean that it represents a valid assigned character.
Practical Importance of Character Encoding
Character encoding is fundamental to modern computing.
Web pages depend on correct text encoding so that browsers can display content properly. Databases use character encodings to store multilingual information. Programming languages use character representations when manipulating strings. File formats also depend on encoding rules to interpret textual data correctly.
Encoding problems can produce strange symbols, missing characters, or unreadable text. Understanding code points and encodings makes these problems easier to identify.
For example, if a document created using one encoding is incorrectly interpreted using another encoding, the displayed characters may not match the original text. This is why modern software generally relies heavily on Unicode and standardized encodings such as UTF-8.
Simple Code Point Calculation Examples
Consider a few basic examples.
Example 1: Find the code point of E
A has decimal code point 65.
E is the fifth letter.
Therefore:
65 + (5 − 1) = 69
So:
E = 69 = U+0045
Example 2: Find the lowercase version of D
D has a decimal code point of 68.
The lowercase difference is 32.
Therefore:
68 + 32 = 100
So:
d = 100 = U+0064
Example 3: Find the difference between C and H
C = 67
H = 72
Therefore:
72 − 67 = 5
The code point difference is 5.
Example 4: Convert U+0042 to decimal
The hexadecimal value is 42.
Therefore:
4 × 16 + 2 = 66
So:
U+0042 = 66 decimal
This is the code point of B.
Why Character Encoding Matters in Computer Science
Character encoding connects several important areas of computer science.
It is related to:
Data representation
Binary numbers
Programming
Web development
Databases
File storage
Data transmission
Internationalization
Text processing
Operating systems
Learning character encoding also provides a practical example of how abstract information is converted into numerical data that computers can manipulate.
A letter such as A seems simple to a human reader, but a computer needs a defined numerical representation to store and process it. Character encoding provides that representation.
Conclusion
Character encoding is the system that allows computers to represent human-readable text as digital data. A code point provides a numerical identity for a character, while an encoding such as UTF-8 determines how that code point is represented in bytes.
ASCII provides a simple foundation for understanding character values, while Unicode extends character representation to languages and symbols used around the world. Basic calculations can involve converting hexadecimal code points to decimal values, finding differences between code points, or determining relationships between uppercase and lowercase English letters.
Understanding these concepts is useful for anyone learning computer science because text is ultimately stored and processed as numerical data. Once the difference between characters, code points, and encoded bytes becomes clear, many aspects of text processing and digital data representation become much easier to understand.
FAQs
1. What is character encoding?
Character encoding is a system that represents text characters as numerical data that computers can store, process, and transmit. Computers work with digital values rather than directly understanding letters and symbols. An encoding system provides rules for converting characters into numerical representations and, eventually, binary data. Common encoding systems include ASCII and Unicode-based encodings such as UTF-8. For example, the character A has the Unicode code point U+0041 and the decimal value 65. Character encoding is essential for displaying text correctly in websites, applications, databases, documents, and other digital systems. Without compatible encoding, text may appear incorrectly or become unreadable.
2. What is a Unicode code point?
A Unicode code point is a numerical value assigned to a character within the Unicode standard. It provides a unique numerical identity for characters from many writing systems, symbols, and other forms of text. Unicode code points are normally written using hexadecimal notation with the prefix U+. For example, the uppercase letter A is represented as U+0041, while lowercase a is U+0061. The hexadecimal number identifies the code point, not necessarily the number of bytes used to store the character. Encoding formats such as UTF-8 then determine how that code point is represented as actual computer data.
3. What is the difference between a character and a code point?
A character is a textual symbol that humans recognize, such as a letter, number, punctuation mark, or other symbol. A code point is the numerical value assigned to that character within a character set such as Unicode. For example, the character A has the Unicode code point U+0041. The character is what people see and understand, while the code point provides a numerical identity that computers can work with. It is important to remember that a code point is not necessarily the same as the number of bytes used to store the character. Encoding determines that representation.
4. What is ASCII and how is it related to Unicode?
ASCII is an early character encoding standard designed primarily for representing English letters, digits, punctuation marks, and control characters. The original ASCII system contains 128 values, ranging from 0 to 127. For example, uppercase A has the decimal value 65 and lowercase a has the value 97. Unicode is a much larger standard designed to represent characters from languages and writing systems around the world. The first 128 Unicode code points correspond to the original ASCII characters. This compatibility is important because ASCII text can be represented directly within UTF-8 without changing its basic byte values.
5. How do you convert a Unicode code point from hexadecimal to decimal?
Unicode code points are commonly written in hexadecimal notation. To convert a hexadecimal value to decimal, multiply each digit by its corresponding power of 16 and add the results. For example, U+0041 contains the hexadecimal value 41. The calculation is: 4 × 16 + 1 × 1 = 65. Therefore, U+0041 has the decimal value 65. Another example is U+0061. The calculation is 6 × 16 + 1 = 97. Therefore, U+0061 has the decimal value 97, which represents the lowercase letter a. Understanding hexadecimal-to-decimal conversion is useful when studying character codes.
6. What is the code point of the letter A?
The Unicode code point of the uppercase English letter A is U+0041. The hexadecimal value 41 corresponds to decimal 65. Therefore, A can be represented as U+0041 or decimal code point 65. In UTF-8, the character A is encoded using one byte with the hexadecimal value 41. The code points for the uppercase English alphabet are consecutive, so B is U+0042, C is U+0043, and so on. This sequence makes simple code point calculations possible. For example, the code point of D can be calculated by adding three to the code point of A.
7. Are code points and bytes the same thing?
No. A code point and a byte represent different concepts. A Unicode code point identifies a character numerically, while an encoding such as UTF-8 determines how that code point is represented using bytes. For example, A has the code point U+0041, and its UTF-8 representation requires one byte, 41 in hexadecimal. However, many Unicode characters require multiple bytes when encoded using UTF-8. Therefore, one character does not always equal one byte. Understanding this difference is especially important when working with file sizes, databases, programming languages, web pages, and systems that process multilingual text.
8. How are uppercase and lowercase code points related?
For the English alphabet, corresponding uppercase and lowercase letters have a difference of 32 in their decimal Unicode code points. For example, uppercase A has the value 65, while lowercase a has the value 97. The difference is 97 − 65 = 32. Similarly, B is 66 and b is 98. Therefore, for these English letters, the lowercase code point can be found by adding 32 to the uppercase code point. This relationship is useful in basic programming and character-conversion exercises. However, this simple numerical relationship should not be generalized to every writing system or every Unicode character.
9. Why does UTF-8 use different numbers of bytes for different characters?
UTF-8 is designed to represent the full Unicode range while remaining compatible with ASCII. It uses between one and four bytes for a Unicode code point. Characters in the ASCII range use one byte, while many other characters require two, three, or four bytes. This variable-length design makes UTF-8 efficient for text that contains many common English characters while still supporting characters from languages and writing systems around the world. For example, A requires one UTF-8 byte, while many non-ASCII characters require multiple bytes. Therefore, the number of bytes used depends on the character’s Unicode code point.
10. Why is character encoding important in computer science?
Character encoding is important because computers need a standardized way to store, process, and transmit text. Without compatible encoding systems, the same data could be interpreted differently by different programs or devices. Character encoding is used in websites, software applications, databases, operating systems, documents, and communication systems. Unicode provides a broad standard for representing characters from languages around the world, while UTF-8 provides a practical way to encode Unicode text as bytes. Learning about characters, code points, and encoding also helps students understand data representation, programming, text processing, and common problems such as incorrectly displayed or corrupted text.