An average is one of the most commonly used mathematical tools for understanding data. It helps summarize a collection of numbers into a single value, making information easier to compare and interpret. A teacher may calculate the average marks of a class, a company may report the average salary of its employees, and a scientist may use an average to summarize experimental measurements. However, an average does not always provide a complete or accurate picture of a dataset.
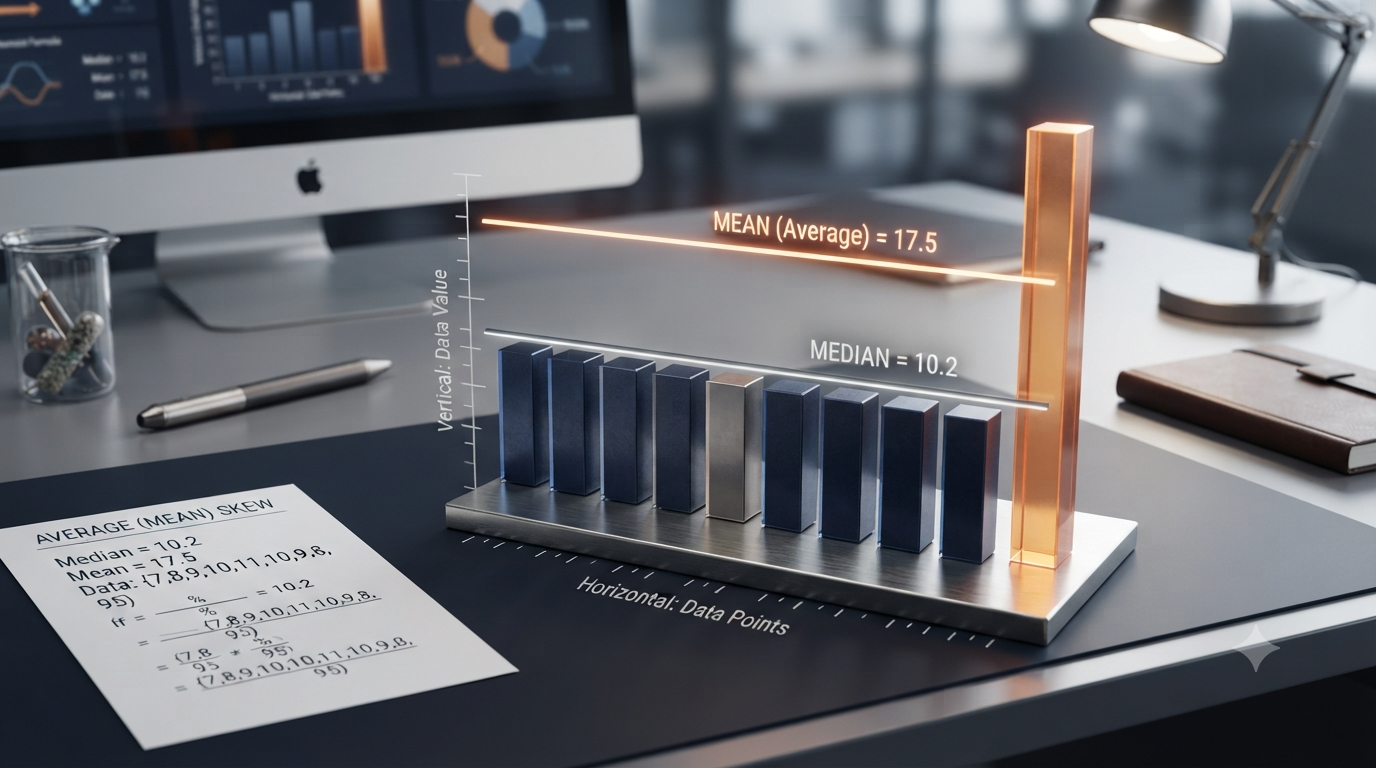
The main problem occurs when a dataset contains extreme values, also known as outliers. These values are unusually high or low compared with the other observations. Because the arithmetic mean depends on every value in a dataset, even one extreme observation can significantly change the result. Consequently, an average may suggest that a group is performing better, earning more, or experiencing different conditions than most of its members actually are.
Understanding why averages can be misleading helps us interpret statistics more carefully and choose more appropriate methods for analyzing data.
What Is an Average?
In everyday mathematics, the word average usually refers to the arithmetic mean. It is calculated by adding all the observations in a dataset and dividing the total by the number of observations.
For example, consider the following five numbers:
10, 12, 14, 16, 18
The sum of these numbers is 70, and there are five observations. Therefore, the average is 14.
Formula for the arithmetic mean
Mean = Sum of all observations / Number of observationsIn mathematical notation:
x̄ = Σx / nHere:
x̄ represents the arithmetic mean.
Σx represents the sum of all observations.
n represents the total number of observations.
The mean provides a useful summary when the values are reasonably balanced. However, its behavior changes when one or more observations are extremely different from the rest.
What Are Extreme Values in a Dataset?
Extreme values are observations that lie unusually far from most other values in a dataset. They may be much larger or much smaller than the typical observations.
For example, consider the following monthly incomes, expressed in thousands of rupees:
20, 22, 23, 24, 26
These values are relatively close to one another. Now imagine that another individual with a monthly income of ₹500,000 is added to the group. Expressed in thousands of rupees, the dataset becomes:
20, 22, 23, 24, 26, 500
The value 500 is much larger than the other observations. It is an extreme value because it lies far away from the general pattern of the data.
Extreme values are often called outliers, although not every unusually high or low observation is necessarily an error. Some outliers occur naturally, while others result from measurement mistakes, data-entry errors, or unusual circumstances.
For example, an unusually high salary may be a genuine observation, while a temperature recorded as 850°C instead of 85°C may indicate a data-entry error. Both values can affect the mean, but they require different explanations.
How Extreme Values Affect the Average
The arithmetic mean is sensitive to extreme values because every observation contributes directly to the total. When a very large value is added to a dataset, the sum increases substantially. When the sum is divided by the number of observations, the resulting mean may move far away from the values that most people or objects actually have.
Consider the following dataset:
10, 12, 13, 15, 15
The sum is 65, and the number of observations is five.
Mean = 65 / 5
The average is 13, which reasonably represents the center of this group.
Now replace the last observation with an extreme value of 100:
10, 12, 13, 15, 100
The sum becomes 150, while the number of observations remains five.
Mean = 150 / 5
The average increases from 13 to 30. However, four out of the five observations are still between 10 and 15.
This is the central problem: the average has increased dramatically, even though most of the observations remain concentrated in a narrow range.
The mean is mathematically correct in both cases. It is misleading only when someone interprets it as a typical value without considering the distribution of the data.
Example 1: Average Salary Can Give a False Impression
Salary statistics provide a clear example of how extreme values can distort an average.
Imagine a small company with five employees whose monthly salaries are:
₹20,000, ₹22,000, ₹24,000, ₹26,000, and ₹28,000.
The total monthly salary is ₹120,000.
Mean salary = ₹120,000 / 5
The average salary is ₹24,000, which is close to the salaries of all five employees.
Now suppose the company hires a chief executive who receives ₹200,000 per month. The new dataset is:
₹20,000, ₹22,000, ₹24,000, ₹26,000, ₹28,000, and ₹200,000.
The total becomes ₹320,000, and there are six employees.
Mean salary = ₹320,000 / 6
The average salary rises to approximately ₹53,333 per month.
However, five of the six employees earn between ₹20,000 and ₹28,000. None of these five employees earns anything close to the new average.
If a report states that the average employee earns more than ₹53,000 per month, readers might assume that most employees receive a salary near that amount. In reality, the unusually high salary of one person has pulled the mean upward.
This example demonstrates why the mean alone may provide an incomplete picture of income distribution. Median salary, salary ranges, and information about how many employees fall into different salary groups can provide a more useful description.
Example 2: Extreme Marks Can Distort Class Performance
Suppose five students receive the following marks in a test out of 100:
60, 62, 65, 68, 70
The average is:
Mean = 325 / 5
An average of 65 reasonably summarizes the performance of this group.
Now imagine that one additional result is entered as 500 instead of a valid mark out of 100. The dataset becomes:
60, 62, 65, 68, 70, 500
The calculated mean is:
Mean = 825 / 6
The resulting average is 137.5, which is impossible for a test scored out of 100.
This example represents a data-quality problem rather than an ordinary statistical outlier. It shows why unusual values should be investigated before interpreting the mean.
Consider a different situation in which one student genuinely scores 100 while the other students receive 60, 62, 65, 68, and 70. The mean becomes approximately 70.83.
This result is mathematically valid, but it still does not show that most students scored around 71. Five students scored between 60 and 70, while only one achieved 100.
Teachers therefore need to examine the distribution of marks rather than relying entirely on the average. The median, score range, and frequency of marks can reveal additional information about class performance.
Why the Mean Is More Sensitive Than the Median
The median is another measure of central tendency. It identifies the middle observation after the data have been arranged in ascending or descending order.
For an odd number of observations, the median is the middle value. For an even number of observations, it is the mean of the two middle values.
Consider the dataset:
10, 12, 13, 15, 100
The mean is 30, but the median is 13.
Median = 13The median remains close to the majority of the observations because it depends on the position of the values rather than the magnitude of every observation.
Now increase the extreme value from 100 to 1,000:
10, 12, 13, 15, 1,000
The mean becomes 210, but the median remains 13.
Mean = 1,050 / 5
Median = 13The mean changes substantially, while the median stays the same.
This difference makes the median particularly useful for skewed datasets, income distributions, property prices, and other situations in which a small number of observations are much larger or smaller than the rest.
However, the median is not always better. If the data are approximately symmetric and contain no influential outliers, the mean can be an informative and efficient measure of the center. The most suitable measure depends on the purpose of the analysis and the structure of the data.
How the Distribution of Data Changes the Meaning of an Average
A single average cannot describe every important feature of a dataset. To understand why, it is helpful to distinguish between three common types of distributions.
1. Approximately Symmetric Distribution
In a symmetric distribution, values are spread relatively evenly around the center. The mean and median are often similar.
For example:
20, 25, 30, 35, 40
The mean and median are both 30.
In this situation, the mean provides a reasonable summary of the central value because neither side of the distribution contains an unusually influential observation.
2. Right-Skewed Distribution
A right-skewed distribution contains a long tail toward larger values. A small number of unusually high observations can pull the mean to the right.
For example:
10, 12, 13, 15, 50
The mean is 20, while the median is 13.
Most values are between 10 and 15, but the high value of 50 increases the average. Income, wealth, and some property-price distributions can show this pattern.
3. Left-Skewed Distribution
A left-skewed distribution contains a longer tail toward smaller values. A small number of unusually low observations can pull the mean downward.
For example:
2, 40, 42, 44, 46
The mean is 34.8, while the median is 42.
Most values lie between 40 and 46, but the low value of 2 reduces the mean. Similar patterns may occur when most participants perform well on a test but a few receive exceptionally low scores.
Recognizing the distribution helps analysts understand whether the mean represents the typical observation or is being influenced by a tail of extreme values.
Other Problems Caused by Relying Only on the Average
Extreme values are not the only reason an average can be misleading. Several other limitations can affect its interpretation.
The Average Hides Differences Between Individuals
Two groups can have the same mean but very different distributions.
For example, consider these two datasets:
Dataset A: 48, 49, 50, 51, 52
Dataset B: 10, 30, 50, 70, 90
Both have a mean of 50. However, the observations in Dataset A are closely grouped, while those in Dataset B are widely spread.
The mean alone cannot show this difference. Measures such as the range, interquartile range, and standard deviation help describe how much the observations vary.
The Average Can Hide Important Subgroups
A large dataset may contain several different groups. For example, the average salary across an entire organization may combine employees in entry-level, managerial, and executive positions.
The overall mean may not accurately represent any one of these groups.
Similarly, the average temperature across a region may hide differences between coastal, mountainous, and inland locations. Breaking data into meaningful subgroups can provide a clearer interpretation.
The Average Does Not Explain the Cause of an Extreme Value
An extreme observation may represent a genuine event, a measurement error, or a different underlying process.
For example, one unusually high electricity bill may result from a heatwave, faulty equipment, or an incorrect meter reading. The mean alone cannot determine which explanation is correct.
Additional information and careful investigation are necessary to understand why the value is unusual.
The Average Can Be Confused With a Typical Experience
A statistical average describes a calculation, not necessarily the experience of a typical person.
For example, the average waiting time at a hospital might be 40 minutes. Some patients may wait only 10 minutes, while others may wait several hours. Reporting only the mean hides this variation.
A median waiting time and information about long waits may provide a more complete understanding of the service.
How to Analyze Data When Extreme Values Are Present
When a dataset contains extreme values, the best approach is not automatically to remove them. Instead, the data should be examined carefully, and the summary measure should be chosen according to the purpose of the analysis.
1. Calculate Both the Mean and the Median
Comparing the mean with the median is a simple way to identify whether unusually high or low observations may be affecting the center of a dataset.
If the mean is much higher than the median, high values may be pulling the average upward. If the mean is much lower than the median, low values may be pulling it downward.
This difference is a useful clue, although it does not prove that an outlier exists.
2. Examine the Data Using a Graph
A histogram, box plot, or dot plot can show how observations are distributed.
A histogram reveals whether the data are symmetric or skewed. A box plot can help identify observations that lie unusually far from the middle portion of the distribution.
Visual inspection is especially helpful because two datasets can have the same mean but very different patterns.
3. Investigate Unusual Observations
Check whether extreme values are valid.
If a value results from a typing mistake, faulty equipment, or incorrect data collection, it may need to be corrected using reliable evidence. If the value is genuine, it should generally remain in the analysis unless there is a clear, justified reason to exclude it.
Removing a genuine extreme value simply because it changes the average can lead to inaccurate conclusions.
4. Use the Median When Appropriate
The median is often a better measure of a typical observation when data are strongly skewed or contain influential extreme values.
For example, median household income can help describe the center of an income distribution without allowing a small number of very wealthy households to dominate the result.
Nevertheless, the median should be selected because it suits the data and research question, not merely because it produces a preferred result.
5. Report More Than One Statistic
A stronger statistical summary often includes several complementary measures.
For example, a report may present the mean, median, minimum, maximum, and a measure of variability. Depending on the data, it may also include the interquartile range, standard deviation, or selected percentiles.
Together, these statistics provide a clearer picture of both the center and the spread of the observations.
6. Consider a Trimmed Mean in Suitable Cases
A trimmed mean is calculated by removing a specified proportion of the lowest and highest observations before calculating the mean.
For example, a researcher might remove the lowest 10% and highest 10% of observations when the analysis method and study design justify doing so.
This approach can reduce the influence of extreme values. However, the trimming rule should be established transparently and applied consistently. It is not appropriate to remove observations selectively simply to obtain a desired result.
When Is the Arithmetic Mean Still Useful?
Despite its sensitivity to extreme values, the arithmetic mean remains an important statistical measure.
It is particularly useful when the data are reasonably balanced, the observations are measured on a meaningful numerical scale, and the objective is to calculate the overall average.
For example, the mean is commonly used to calculate average experimental measurements, average production output, average marks, and average daily energy consumption.
It is also important in many statistical methods, including variance calculations, regression analysis, and the estimation of population quantities.
Even when a dataset contains extreme values, the mean may still be the correct measure if those values are genuine and the goal is to understand the overall arithmetic balance of the observations.
For instance, if a business wants to calculate its total payroll divided by the number of employees, the mean salary answers that specific question. The median answers a different question about the middle employee’s salary.
The key is to understand what the average measures and whether it answers the question being asked.
Conclusion
An average can be misleading when a dataset contains extreme values because the arithmetic mean is sensitive to every observation. A single unusually high or low value can shift the mean away from the range where most observations are concentrated. As a result, the average may not represent the experience of a typical person, student, employee, or measurement.
Comparing the mean with the median, examining graphs, investigating unusual observations, and reporting measures of variability can help prevent incorrect conclusions. The median is often more representative when data are strongly skewed, while the mean remains useful when the overall arithmetic balance is important.
Ultimately, an average should not be interpreted in isolation. Understanding the distribution, checking the quality of the data, and selecting an appropriate statistical measure are essential steps in making reliable decisions based on numerical information.
FAQs
1. Why can an average be misleading when a dataset contains extreme values?
An average can be misleading because the arithmetic mean is affected by every value in a dataset. When an extremely high or low value is included, it can pull the mean away from the values that most observations represent. For example, if most employees earn ₹25,000 per month but one executive earns ₹200,000, the average salary may become much higher than what most employees receive. Although the calculated mean is mathematically correct, it may not describe a typical employee’s salary. Therefore, the median and data distribution should also be considered when interpreting an average.
2. What are extreme values in statistics?
Extreme values are observations that are unusually high or low compared with the other values in a dataset. They may occur naturally or result from measurement errors, incorrect data entry, or unusual circumstances. For example, if most students score between 60 and 80 marks, a score of 100 may be relatively high, while a mistakenly recorded score of 500 would be an invalid extreme value for a test out of 100. Extreme values are often called outliers, although their identification depends on the dataset and context. Examining them helps researchers understand the data and avoid incorrect conclusions.
3. How do extreme values affect the arithmetic mean?
Extreme values can significantly change the arithmetic mean because the mean is calculated by adding all observations and dividing their sum by the number of observations. A very large value increases the total, while a very small value decreases it relative to the other observations. For example, the mean of 10, 12, 13, 15, and 100 is 30. However, four of these five values are between 10 and 15. This demonstrates that the mean can move far away from most observations. The magnitude of an extreme value determines how strongly it influences the result.
4. What is the difference between the mean and the median?
The mean is calculated by adding all observations and dividing the total by the number of observations. The median is the middle value when the observations are arranged in ascending or descending order. The main difference is their sensitivity to extreme values. For example, in the dataset 10, 12, 13, 15, and 100, the mean is 30, whereas the median is 13. The median remains close to most observations because it depends on their positions rather than their magnitudes. Both measures are useful, but the median is often more representative when data contain influential outliers.
5. Why is the median often better than the mean for income data?
The median is often better for describing typical income because income distributions commonly contain a small number of very high earners. These unusually large incomes can raise the mean considerably, making average earnings appear higher than the income received by most people. The median identifies the middle income when all incomes are arranged in order, so a few extremely high salaries generally have little effect on it. However, the mean is still useful when calculating total income divided by the number of people. Reporting both measures provides a more complete understanding of income distribution and inequality.
6. Can an average be mathematically correct but still misleading?
Yes, an average can be mathematically correct while creating a misleading impression. The calculation may follow the correct formula, but the result might not represent a typical observation. For example, a company with several employees earning ₹20,000 to ₹30,000 and one executive earning ₹200,000 may report an average salary far above what most employees receive. The mean itself is not incorrect; the problem occurs when readers interpret it without considering the distribution. To avoid misunderstanding, statistical reports should explain what the average represents and may also include the median, range, and other measures of variability.
7. How can you identify whether extreme values are affecting an average?
One simple method is to compare the mean and median. A substantial difference between them may indicate that unusually high or low observations are influencing the mean. However, this difference alone does not prove that outliers exist. Graphs such as histograms, dot plots, and box plots can reveal unusual observations and patterns of skewness. Researchers should also examine the original data to identify possible measurement or recording errors. By combining numerical comparisons, visual analysis, and contextual knowledge, it becomes easier to determine whether extreme values affect the average and whether another statistical measure would be more suitable.
8. Should extreme values always be removed before calculating an average?
No, extreme values should not automatically be removed. Some represent genuine and important observations, such as unusually high incomes, exceptional scientific measurements, or rare environmental events. Removing them without justification can distort the dataset and produce inaccurate conclusions. However, if an extreme value results from a confirmed recording or measurement error, correcting or excluding it may be appropriate. Researchers should investigate unusual observations and document any changes transparently. When genuine extreme values strongly influence the mean, comparing it with the median or using a justified alternative, such as a trimmed mean, may provide a more balanced interpretation.
9. What other statistical measures can help when an average is misleading?
Several statistical measures can provide additional information when the mean does not adequately describe a dataset. The median identifies the middle observation and is less sensitive to extreme values. The range shows the difference between the maximum and minimum values, while the interquartile range describes the spread of the middle 50% of observations. Standard deviation measures how widely observations vary around the mean and can itself be sensitive to outliers. Percentiles can show where individual observations fall within a distribution. Using suitable combinations of these measures helps researchers understand the center, spread, and structure of data more accurately.
10. When should you use the mean instead of the median?
The mean is useful when the goal is to calculate the overall arithmetic balance of numerical observations. It is often appropriate when data are reasonably symmetric and extreme values do not dominate the distribution. For example, the mean can summarize repeated laboratory measurements or calculate average production output. It is also important in many statistical calculations, including variance and regression analysis. The median is generally preferable when data are strongly skewed or contain influential outliers and the goal is to describe a typical observation. Choosing between them depends on the dataset, the research question, and the meaning of the result.