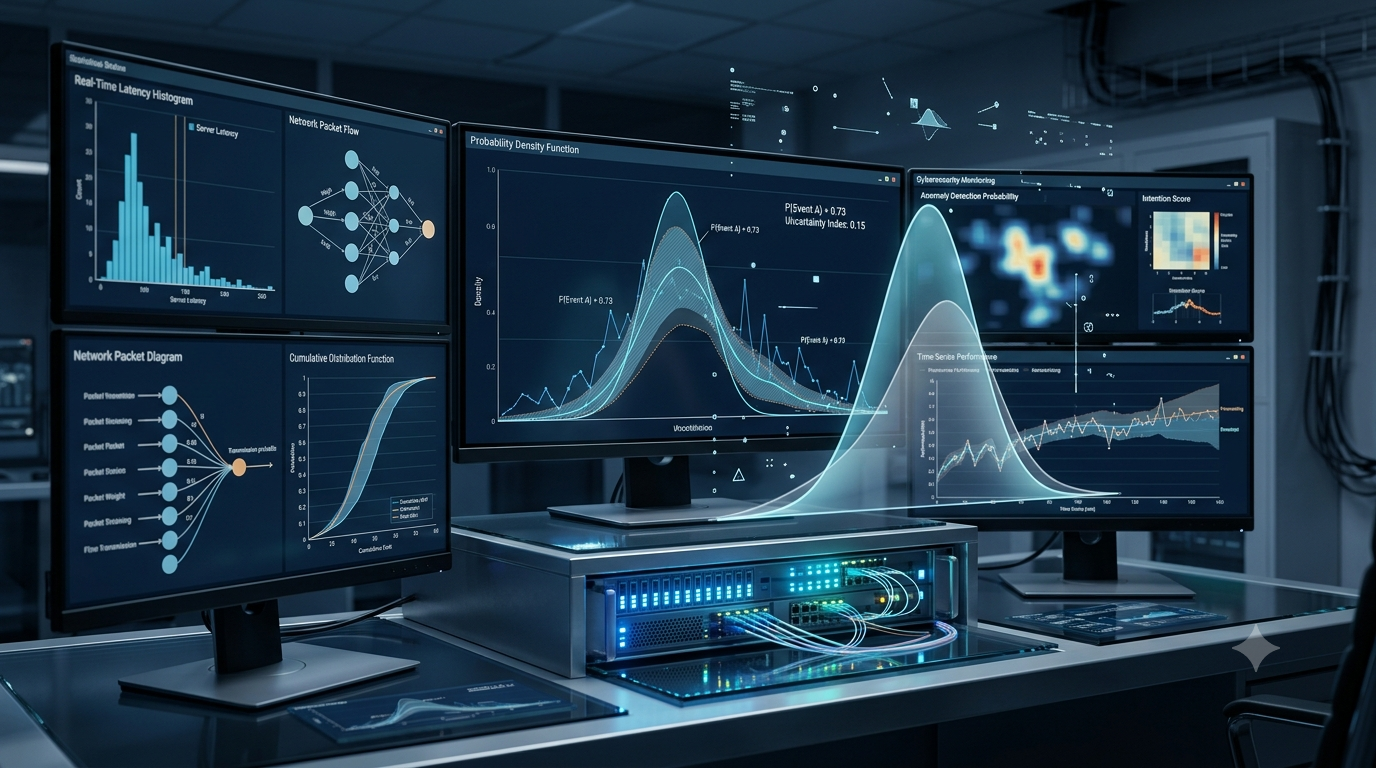
Computer systems perform millions of operations every second, but their behavior is not always perfectly predictable. A network connection may fail, a server may receive an unexpected number of requests, a database query may take longer than expected, or a machine learning model may produce different predictions for different inputs. These situations involve uncertainty, which means that the exact outcome is not known in advance.
Probability provides a mathematical way to describe and measure this uncertainty. Instead of simply saying that something might happen, probability helps estimate how likely an event is to occur. It allows computer scientists and engineers to analyze system reliability, network performance, cybersecurity risks, data processing, and many other aspects of computing.
Understanding probability is especially important when designing systems that must operate reliably under changing conditions. By using probability, developers can make informed decisions, compare possible outcomes, estimate risks, and build computer systems that perform more effectively in real-world situations.
What Is Uncertainty in Computer Systems?
Uncertainty in a computer system exists when the exact outcome of an operation, event, or process cannot be predicted with complete confidence. Some operations are deterministic, meaning that the same input and conditions produce the same output. Other processes involve random behavior or changing conditions that make their outcomes less predictable.
For example, adding two numbers in a program normally produces a predictable result. However, the time required to transmit a file over a network may change because of congestion, interference, server load, or other factors.
Common examples of uncertainty in computer systems include:
Network packets may arrive late or fail to reach their destination.
Servers may experience unpredictable changes in user traffic.
Storage devices may occasionally encounter errors.
Security systems may detect suspicious activity that requires further investigation.
Machine learning models may assign different confidence levels to their predictions.
Cloud computing resources may experience variable response times.
These situations cannot always be described using a single fixed value. Probability provides a structured method for analyzing how frequently different outcomes may occur and how likely those outcomes are under specified conditions.
What Is Probability?
Probability is a mathematical measure of how likely an event is to occur. Its value ranges from 0 to 1, where 0 represents an impossible event and 1 represents a certain event.
A probability closer to 0 indicates that an event is less likely, while a probability closer to 1 indicates that it is more likely.
Text block: Basic Probability Formula
P(A) = Number of favorable outcomes / Total number of equally likely outcomesHere, P(A) represents the probability of event A. A favorable outcome is an outcome that satisfies the condition being studied.
For example, suppose a computer system has 100 network packets, and historical observations suggest that approximately 5 packets are lost under certain operating conditions. The estimated packet-loss probability is:
Text block: Packet Loss Probability Example
P(Packet Loss) = 5 / 100
This result suggests that approximately 5% of packets may be lost under similar conditions. It does not mean that exactly 5 packets will always be lost in every group of 100 packets.
In real computer systems, probabilities are often estimated from historical measurements, statistical models, simulations, or known characteristics of the system. These estimates help developers understand possible outcomes without needing to predict every individual event.
How Probability Represents Uncertainty
Probability converts uncertainty into a numerical value that can be analyzed and compared. Instead of describing a system as unreliable or unpredictable, engineers can estimate the likelihood of specific events.
For example, consider two servers with different observed failure probabilities. Server A has an estimated daily failure probability of 0.01, while Server B has an estimated daily failure probability of 0.04.
Text block: Comparing Failure Probabilities
Server A Failure Probability = 0.01 = 1%
Under comparable conditions and using comparable definitions of failure, Server B has a higher estimated probability of failure.
This information can help an organization evaluate its infrastructure, plan maintenance, or decide whether additional redundancy is necessary.
However, probability does not guarantee that an event will or will not occur. Even an event with a low probability can happen, and an event with a high probability may not happen on a particular occasion.
Probability therefore describes uncertainty rather than eliminating it.
Important Probability Concepts in Computing
Several probability concepts are especially useful when analyzing computer systems.
1. Random Events
A random event is an event whose outcome is uncertain before it occurs. In computing, examples include whether a packet will be lost, whether a user will click a particular link, or whether a request will exceed a specified response-time limit.
Random events can be studied by collecting observations and estimating how frequently they occur.
For example, a website administrator might record the number of failed login attempts each hour. These observations can help estimate the likelihood of unusually high login activity and support decisions about security monitoring.
2. Random Variables
A random variable represents a numerical outcome associated with a random process. It allows uncertain events to be expressed mathematically.
For example, let X represent the number of failed requests received by a server during one minute.
Text block: Random Variable Example
X = Number of failed requests per minuteThe variable X might take values such as 0, 1, 2, 3, or higher, depending on the system’s behavior.
By studying the observed values of X, engineers can estimate the average number of failed requests, measure how much the count varies, and identify periods when failures become unusually frequent.
Random variables are useful because they convert unpredictable system behavior into data that can be analyzed using statistical methods.
3. Probability Distributions
A probability distribution describes how probabilities are assigned to the possible values of a random variable.
For example, a server might receive different numbers of requests during different minutes. A probability distribution can describe how likely it is to receive 10, 20, 50, or 100 requests in a given minute.
Different distributions are suitable for different situations. The binomial distribution can model the number of successes in a fixed number of independent trials with the same success probability. The Poisson distribution is often used to model event counts over a fixed interval when its assumptions are reasonable. Normal distributions are useful for some measurements that cluster around an average.
Selecting an appropriate distribution helps engineers build models of system behavior and estimate the likelihood of particular outcomes.
4. Expected Value
Expected value represents the probability-weighted average of the possible values of a random variable. It describes the long-run average outcome that a model predicts, rather than the exact result of an individual trial.
Text block: Expected Value Formula
E(X) = Σ [x × P(X = x)]In this formula, X is a random variable, x represents one of its possible values, and P(X = x) is the probability that X takes that value. The symbol Σ means that the values are added across all possible outcomes.
For example, expected value can help estimate the average number of failed requests per minute or the average cost associated with a system failure.
These estimates are useful for capacity planning, performance analysis, and operational budgeting.
Applications of Probability in Computer Systems
Probability has many practical applications in modern computing. It helps engineers make decisions when exact outcomes are unknown and when system behavior changes over time.
1. Network Reliability and Packet Loss
Computer networks transmit data in packets. During transmission, packets may be lost because of congestion, equipment problems, wireless interference, or other network conditions.
Probability helps estimate the likelihood of packet loss and evaluate network reliability.
Text block: Packet Delivery Probability
P(Packet Delivered) = 1 − P(Packet Lost)If the probability of losing an individual packet is 0.02, then the probability of delivering that packet is estimated as:
P(Packet Delivered) = 1 − 0.02
This calculation assumes that packet delivery and packet loss are the only two possible outcomes for the event being measured.
Engineers can use such estimates to compare network conditions and evaluate whether retransmission mechanisms or other reliability improvements are needed.
For a sequence of packets, however, the probability that all packets arrive successfully depends on their individual probabilities and the relationships between their outcomes. If packet losses are independent and each packet has the same delivery probability, the probability that all n packets arrive successfully is the delivery probability raised to the power n.
2. Server Reliability and System Availability
Servers are expected to provide services consistently, but failures and maintenance periods can interrupt operations.
Probability helps engineers estimate the likelihood of component failures and assess the reliability of different system designs.
For example, a server with a lower probability of failure during a specified period may be preferable to one with a higher estimated failure probability, assuming other important factors are comparable.
Probability is also relevant to system availability, which describes how often a service is operational and accessible. Availability is not simply the inverse of failure probability in every situation; it also depends on how long failures last and how quickly services recover.
By analyzing failure frequency and recovery time, organizations can plan backups, redundancy, monitoring, and disaster recovery procedures.
3. Cybersecurity and Threat Detection
Cybersecurity systems must distinguish ordinary activity from potentially harmful behavior. However, suspicious activity does not always indicate an attack, and some attacks may resemble legitimate operations.
Probability helps security teams evaluate how likely certain events are under different conditions.
For example, a system might detect repeated login failures from an unfamiliar location. This activity may increase the estimated likelihood of an account attack, but it does not prove that an attack is taking place.
Statistical models can combine several indicators, such as login frequency, device information, location changes, and historical account behavior, to help prioritize investigations.
Probability is also important when evaluating security alerts. A detector that generates many false positives may overwhelm security teams, while a detector that misses genuine attacks may create serious risks.
4. Database Performance and Query Processing
Database systems handle requests whose execution times may vary depending on data size, indexing, memory availability, storage performance, and concurrent users.
Probability can help estimate the likelihood that a query will exceed a response-time target.
For example, a database administrator might measure query execution times over thousands of requests. The resulting data can be used to estimate the probability that a query takes longer than 500 milliseconds.
Text block: Response Time Probability
P(X > 500 ms)Here, X represents the query execution time. The expression describes the probability that execution takes more than 500 milliseconds.
This information helps developers identify performance problems and establish service-level objectives. It can also guide decisions about indexing, caching, database scaling, and query optimization.
5. Cloud Computing and Resource Allocation
Cloud computing platforms must allocate computing resources according to changing demand. User traffic can rise unexpectedly during product launches, special events, or periods of high activity.
Probability helps estimate the likelihood of traffic spikes and resource shortages.
For example, historical traffic patterns may show that a website occasionally receives several times its normal number of requests. A probabilistic model can help estimate how often such increases may occur and how much additional capacity might be needed.
These estimates support decisions about autoscaling, load balancing, resource reservations, and cost management.
The predictions remain estimates. Sudden events that differ substantially from historical patterns can still produce unexpected demand.
6. Machine Learning and Artificial Intelligence
Machine learning systems often make predictions from incomplete or uncertain information. A classification model, for example, may estimate the probability that an email is spam or that a transaction is fraudulent.
Text block: Classification Probability Example
P(Spam | Email Features) = 0.92This expression represents the model’s estimated probability that an email is spam, given its observed features.
A value of 0.92 does not automatically mean that the prediction is correct 92% of the time for every individual email. The interpretation depends on whether the model’s probabilities are well calibrated and whether the evaluated data resembles the data encountered in practice.
Probability helps developers establish decision thresholds, compare model predictions, and manage uncertain classifications.
For instance, a security application might send high-risk transactions for additional verification rather than automatically rejecting every transaction that receives a moderately elevated risk score.
7. Error Detection and Data Integrity
Data can be corrupted during transmission, storage, or processing. Error detection methods help identify some forms of corruption, while probability can help estimate how frequently errors occur and how effective a detection method is under a specified error model.
For example, a parity bit can detect any odd number of bit flips within the protected group, but it does not detect every possible corruption pattern. If two bits flip, the parity may remain unchanged.
Probability helps engineers study the likelihood of different error patterns and evaluate the strengths and limitations of data integrity techniques.
This is important in communication networks, storage devices, distributed systems, and applications where accurate data is essential.
Conditional Probability and Dependencies in Computer Systems
Events in a computer system are not always independent. One event may change the probability of another event occurring.
Conditional probability describes the probability of an event when additional information is known.
Text block: Conditional Probability Formula
P(A | B) = P(A ∩ B) / P(B)This formula applies when P(B) is greater than zero. Here, P(A | B) is the probability of event A given event B, and P(A ∩ B) is the probability that both events occur.
For example, suppose a network monitoring system observes that packet loss becomes more common during periods of high congestion. The probability of packet loss given high congestion may be greater than the overall probability of packet loss.
This distinction helps engineers identify the conditions associated with failures.
Conditional probability is also useful in cybersecurity, fault diagnosis, predictive maintenance, and distributed computing, where the state of one component can influence the behavior of another.
Understanding Risk Through Probability
Probability is a key part of risk analysis. However, probability alone does not fully describe risk because the consequences of an event also matter.
A rare event may cause severe damage, while a frequent event may have only a minor impact. Engineers must consider both the likelihood of an event and the consequences associated with it.
Text block: Simplified Expected Loss Formula
Expected Loss = P(Event) × Loss if Event OccursSuppose a particular failure has an estimated probability of 0.01 during a defined period and would cause a loss of ₹100,000 if it occurred.
Expected Loss = 0.01 × ₹100,000
The result is an expected monetary loss of ₹1,000 for that period under the model’s assumptions.
This does not mean that the organization will actually lose ₹1,000. The actual loss may be zero or ₹100,000, depending on whether the event occurs. The expected value is useful for comparing risks and evaluating preventive measures.
In practice, risk analysis may also need to consider multiple possible consequences, recurring events, dependencies, recovery costs, and uncertainty in the probability estimates themselves.
Limitations of Probability in Computer Systems
Although probability is powerful, it has limitations. A probability estimate is only as reliable as the data, assumptions, and model used to produce it.
Historical data may not represent future operating conditions. A server that rarely failed in the past may encounter a new software defect after an update. A network model developed for normal traffic may perform poorly during an unusual surge in demand.
Another important limitation is the assumption of independence. Some calculations assume that events occur independently, but real computer failures may be correlated. For example, two servers in the same data center might fail together because they depend on the same power supply or network connection.
Small datasets can also produce misleading estimates. Observing no failures in a short test does not prove that a system has zero failure probability.
To use probability effectively, engineers should collect sufficient data, validate their assumptions, examine unusual conditions, and update their models as new evidence becomes available. They should also communicate the uncertainty surrounding estimates instead of treating predictions as guarantees.
Conclusion
Probability provides a mathematical foundation for understanding uncertainty in computer systems. It helps describe the likelihood of events such as packet loss, server failures, security threats, database delays, and incorrect machine learning predictions. Concepts such as random variables, probability distributions, expected value, and conditional probability allow engineers to analyze system behavior and make evidence-based decisions.
Probability cannot eliminate uncertainty or guarantee that a particular outcome will occur. Instead, it helps quantify what is known, estimate what may happen, and identify where additional protection or investigation may be necessary.
By combining probability with reliable data, appropriate statistical models, and practical engineering judgment, computer scientists can design systems that are more reliable, secure, efficient, and prepared for unexpected situations.
FAQs
1. What is probability in computer systems?
Probability in computer systems is a mathematical method used to measure how likely an event is to occur. It helps describe uncertain situations, such as network failures, server downtime, data corruption, and unpredictable response times. Probability values range from 0 to 1, where 0 represents an impossible event and 1 represents a certain event. Computer scientists use probability to analyze system behavior, estimate risks, and make informed decisions. For example, if a network has a packet-loss probability of 0.05, it indicates an estimated 5% chance of losing a packet under the specified conditions. This information supports reliability and performance improvements.
2. Why is probability important for understanding uncertainty in computing?
Probability is important because computer systems operate under changing conditions that cannot always be predicted precisely. Network congestion, changing workloads, hardware faults, and unexpected user activity can influence system performance. Probability helps engineers estimate how likely these events are and prepare suitable responses. For example, a cloud service provider can analyze traffic patterns to estimate the likelihood of sudden demand increases. These estimates support resource allocation, capacity planning, and reliability improvements. Probability also helps compare alternative system designs by examining their estimated risks. Although it cannot guarantee future outcomes, it provides a structured mathematical approach to making decisions under uncertainty.
3. How is probability calculated in computer systems?
Probability can be calculated by dividing the number of favorable outcomes by the total number of equally likely outcomes. This basic formula applies when the possible outcomes are equally likely and the sample space is appropriately defined. In practical computing, probabilities are frequently estimated from observed data. For example, if 20 packets are lost among 1,000 transmitted packets, the observed packet-loss rate is 20 divided by 1,000, or 0.02. This corresponds to 2%. The estimate describes the observed sample, not a guarantee about future transmissions. Larger, representative datasets can help engineers estimate system behavior more reliably.
4. What is the difference between probability and uncertainty?
Uncertainty refers to a lack of complete knowledge about an outcome, while probability provides a mathematical way to describe the likelihood of specified outcomes. For example, a server administrator may be uncertain about whether a server will fail during the next hour. Probability can help estimate the chance of failure using historical observations and system information. However, probability does not remove uncertainty or ensure a particular result. An estimated failure probability of 1% still allows a failure to occur. Understanding this distinction helps computer scientists interpret predictions correctly, communicate risks clearly, and avoid treating statistical estimates as certain facts.
5. How does probability help improve network reliability?
Probability helps network engineers estimate packet loss, transmission failures, and other communication problems. By measuring how frequently these events occur, engineers can identify unreliable network conditions and evaluate possible improvements. For example, an observed packet-loss probability of 0.02 indicates that approximately 2% of packets were lost under the measured conditions. Engineers may investigate congestion, signal interference, faulty equipment, or routing problems. Probability can also help evaluate retransmission methods and redundant communication paths. However, packet losses may be dependent on one another, particularly during congestion. Therefore, accurate network reliability analysis should consider operating conditions, dependencies, and representative measurements.
6. How is probability used to measure server reliability?
Probability helps estimate the likelihood of server failures over a specified period. Engineers can analyze historical failure records, hardware performance, software errors, and workload information to develop reliability estimates. For example, a server might have an estimated 0.01 probability of failure during a particular day under defined operating conditions. This corresponds to a 1% estimated daily failure probability. Such information can help organizations decide whether to introduce redundant servers, improve monitoring, or schedule preventive maintenance. Server reliability also depends on recovery time and shared dependencies. Therefore, probability estimates should be combined with availability measurements and practical testing to evaluate overall service reliability.
7. What is conditional probability in computer systems?
Conditional probability measures the likelihood of an event when another event is already known to have occurred. It is useful when computer system events are related. For example, network packet loss may become more likely when congestion is high. The probability of packet loss under congested conditions may therefore differ from the overall packet-loss probability. Conditional probability can also support cybersecurity investigations by evaluating suspicious activity alongside other indicators. Its basic formula is P(A | B) = P(A ∩ B) / P(B), provided P(B) is greater than zero. This approach helps engineers understand dependencies and make more informed predictions about system behavior.
8. How does probability help in cybersecurity?
Probability helps cybersecurity professionals evaluate uncertain threats and identify potentially dangerous activities. Security systems may analyze repeated login failures, unusual access patterns, suspicious network traffic, and unexpected account behavior. Statistical models can combine these observations to estimate the likelihood of malicious activity. For example, several unusual login attempts may increase the estimated probability of an account attack. However, suspicious activity does not automatically prove that an attack has occurred. Probability-based methods help prioritize alerts and investigations, reducing unnecessary responses to harmless activity. Their effectiveness depends on data quality, appropriate thresholds, and regular evaluation to control false positives and avoid missing genuine threats.
9. What is expected value in computer system analysis?
Expected value is the probability-weighted average of the possible outcomes of a random variable. It helps estimate long-run averages for uncertain events, such as failed requests, repair costs, and system downtime. Its basic formula is E(X) = Σ[x × P(X = x)]. Here, X represents a random variable, x represents a possible value, and P(X = x) represents the probability of that value. For example, expected value can help estimate the average number of errors a server may experience during a specified period. It supports capacity planning, performance evaluation, and cost analysis, but does not predict the exact result of an individual event.
10. What are the limitations of using probability in computing?
Probability depends on the quality of available data, the assumptions of the model, and the conditions under which estimates are produced. Historical observations may not represent future situations, particularly when software, hardware, workloads, or security threats change. Some calculations also assume that events are independent, even though real system failures may share common causes. For example, two servers can fail together if both depend on the same power supply. A small sample may also underestimate rare failures. To improve accuracy, engineers should use representative data, validate assumptions, consider dependencies, and update estimates regularly. Probability supports better decisions but cannot guarantee outcomes.