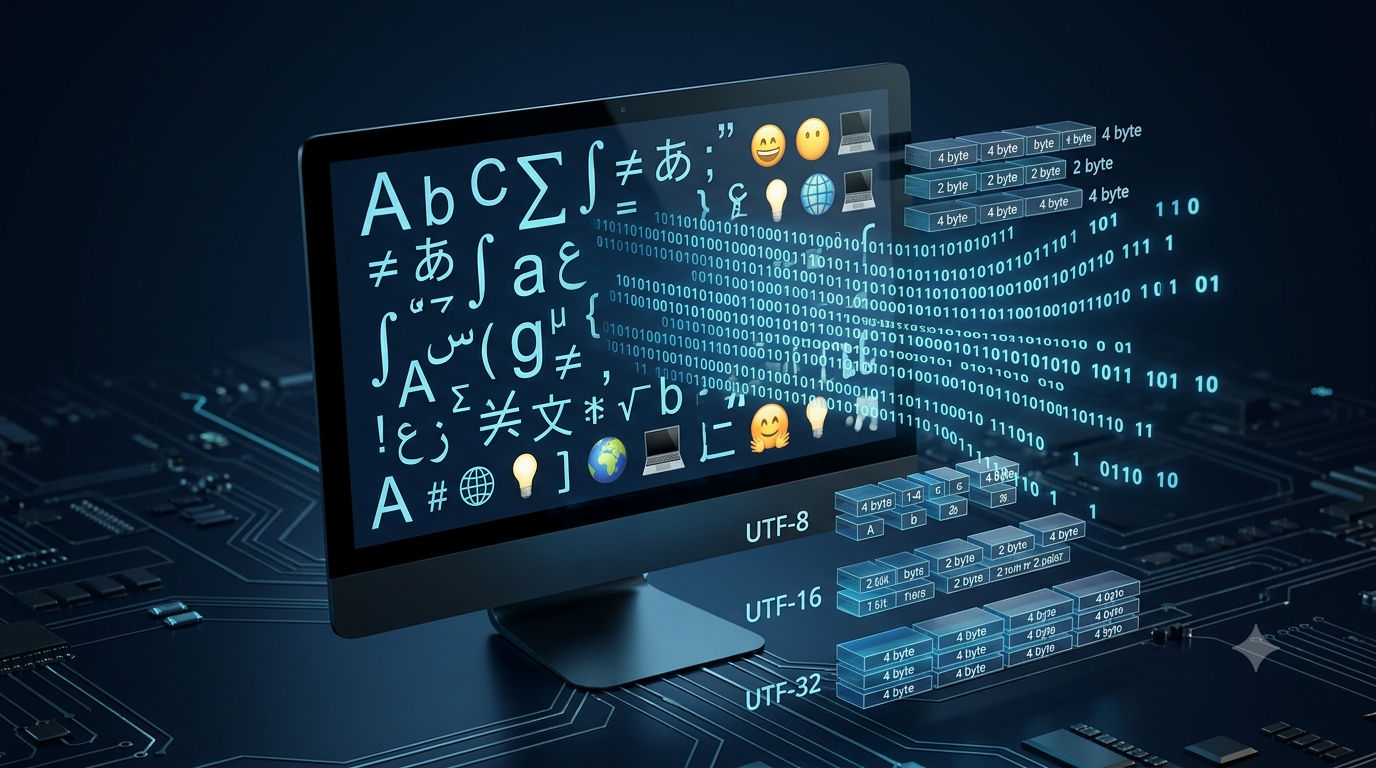
Text may look simple when we read it on a screen, but computers must represent every character using numerical data. Letters, numbers, punctuation marks, symbols, and characters from different languages are stored as binary data, which consists of bits and bytes. The method a computer uses to represent these characters is called character encoding. Different encoding systems can use different numbers of bytes to store the same text, which directly affects the amount of storage required.
For example, the English letter A requires one byte in ASCII and UTF-8. However, many characters from other languages require more bytes in UTF-8. Special symbols and emojis may also need multiple bytes. Understanding character encoding helps explain why two text files containing similar amounts of text can have different file sizes. It is also important in programming, databases, websites, and data transmission.
1. What Is Character Encoding?
Character encoding is a system that maps characters to numerical values so that computers can store, process, and display text.
Humans recognize characters such as A, B, 7, ?, and ₹. Computers, however, work with binary data. Character encoding provides a defined way to represent these characters using numbers and bytes.
For example, in ASCII, the uppercase letter A is represented by the decimal number 65. Its binary representation is 01000001, which occupies eight bits or one byte.
Similarly, the lowercase letter a has the decimal value 97 in ASCII. Although A and a are visually related, they have different numerical representations.
A character encoding system defines how characters are mapped to values and how those values are represented in stored data. Different encoding systems may represent the same character using different amounts of storage.
Common character encoding systems include:
ASCII
UTF-8
UTF-16
UTF-32
Each system has its own representation rules, and these rules influence the size of a text file.
2. Understanding Bits and Bytes
Before exploring how encoding affects storage, it is important to understand the basic units used to measure digital information.
A bit is the smallest standard unit of digital information. It can have one of two values: 0 or 1.
A byte usually consists of eight bits.
Therefore:
1 byte = 8 bits
1 kilobyte (KB) = commonly 1,024 bytes in traditional binary-based usage
1 megabyte (MB) = 1,024 KB in traditional binary-based usage
Storage measurements sometimes use decimal units instead. In the decimal system, 1 kilobyte equals 1,000 bytes and 1 megabyte equals 1,000,000 bytes. The distinction depends on the measurement convention being used.
When a text file is saved, its characters are represented by bytes according to the chosen encoding. The more bytes required to represent the text, the more storage space the encoded text generally occupies.
For example, if a file contains 1,000 characters and every character uses one byte, the character data requires approximately 1,000 bytes. If every character uses four bytes, the same number of characters requires approximately 4,000 bytes.
This is a simplified calculation because actual text may contain characters that use different numbers of bytes, and the file may include additional information.
3. How ASCII Stores Text
ASCII stands for American Standard Code for Information Interchange. It is an early character encoding system designed primarily for English letters, digits, punctuation marks, and control characters.
Standard ASCII defines 128 character values, from 0 to 127. These values can be represented using seven bits, although ASCII text is commonly stored in eight-bit bytes.
For example:
| Character | Decimal value | Binary representation |
|---|---|---|
| A | 65 | 01000001 |
| B | 66 | 01000010 |
| a | 97 | 01100001 |
| 0 | 48 | 00110000 |
Each character in a typical ASCII text file occupies one byte.
Consider the word HELLO. It contains five characters.
Storage calculation:
5 characters × 1 byte = 5 bytes
Therefore, the word HELLO requires five bytes for its character data when stored using a conventional ASCII-compatible representation without additional file information.
ASCII is efficient for basic English text. However, standard ASCII cannot directly represent most accented letters, characters from Indian languages, or many other international writing systems. This limitation led to the development and adoption of more comprehensive encoding systems.
4. How UTF-8 Affects Storage Requirements
UTF-8 is a Unicode encoding format widely used on websites, in software, and in text files. Unicode defines a large collection of characters from many writing systems, including English, Hindi, Marathi, Chinese, Arabic, and numerous symbols and emojis.
UTF-8 uses a variable-length encoding system. This means a character can occupy between one and four bytes.
The number of bytes depends on the character being represented.
Typical UTF-8 storage requirements are:
| Character type | Typical UTF-8 storage |
|---|---|
| Basic English letters | 1 byte |
| Basic English digits | 1 byte |
| Many accented Latin characters | 2 bytes |
| Many characters from other writing systems | 3 bytes |
| Many emojis and supplementary Unicode characters | 4 bytes |
These are common patterns rather than a complete classification of every character.
For example, the word CAT contains three basic English letters. In UTF-8, each letter requires one byte.
3 characters × 1 byte = 3 bytes
Now consider a text containing characters from Marathi or Hindi. Many Devanagari characters require three bytes each in UTF-8. Some written forms also contain multiple Unicode code points, so the storage required for a visible character or written syllable may involve several encoded components.
As a result, a text containing 100 visible characters does not necessarily require 100 bytes.
This is one of the main reasons character encoding affects storage requirements: the number of bytes depends on the characters in the text, not simply on the number of characters a person sees.
5. How UTF-16 and UTF-32 Store Text
UTF-16 and UTF-32 are other Unicode encoding formats. They can represent the same broad range of Unicode characters as UTF-8, but their storage behavior is different.
UTF-16
UTF-16 represents most characters using one 16-bit code unit, which occupies two bytes. Characters outside the Basic Multilingual Plane are represented using two code units, requiring four bytes in total.
For example, a basic English letter such as A generally occupies two bytes in UTF-16. An emoji such as 😀 typically requires four bytes.
Consequently, UTF-16 may use more storage than UTF-8 for text containing mostly English characters. However, the difference depends on the text and the exact characters being stored.
UTF-32
UTF-32 represents every Unicode code point using a fixed-width 32-bit unit, which occupies four bytes.
For example, the letter A requires four bytes in UTF-32, compared with one byte in UTF-8.
This fixed-width approach can make some character-processing operations simpler, but it often requires more storage for ordinary text.
Comparison of the three formats
| Character | UTF-8 | UTF-16 | UTF-32 |
|---|---|---|---|
| A | 1 byte | 2 bytes | 4 bytes |
| é (U+00E9) | 2 bytes | 2 bytes | 4 bytes |
| € (U+20AC) | 3 bytes | 2 bytes | 4 bytes |
| 😀 (U+1F600) | 4 bytes | 4 bytes | 4 bytes |
The table assumes standard representations of these Unicode characters, excluding any file header or byte-order mark.
It demonstrates that the same character can require different amounts of storage depending on the encoding. There is no single encoding that uses the same number of bytes for every character across all formats.
6. Why the Same Text Can Have Different File Sizes
Imagine saving the word SCIENCE in three different Unicode encoding formats.
The word contains seven basic English letters.
In UTF-8:
7 characters × 1 byte = 7 bytes
In UTF-16:
7 characters × 2 bytes = 14 bytes
In UTF-32:
7 characters × 4 bytes = 28 bytes
The character data therefore occupies different amounts of storage, even though the word looks identical in all three files.
Now consider a document containing English, Marathi, mathematical symbols, and emojis. Its total size will depend on the number and types of characters, their encoding, and any additional file information.
A UTF-8 document containing mostly English text may be relatively compact because basic English characters use one byte each. A UTF-16 or UTF-32 version of that document may require more space for the same text.
However, the result can change when the document contains many characters that require multiple bytes in UTF-8. That is why file size should be calculated using the actual encoded content rather than a simple character count.
7. A Practical Example Using Different Languages
Consider three short messages:
English:
HelloHindi:
नमस्तेA message containing an emoji:
Hello 😀
In UTF-8, Hello uses five bytes because each English letter occupies one byte.
The Hindi word नमस्ते contains multiple Unicode code points, including letters and a combining vowel sign. These components generally use three bytes each in UTF-8. Its encoded size is therefore larger than its visible character count might suggest.
The message Hello 😀 contains five English letters, a space, and an emoji. The English letters and space use six bytes altogether, while the emoji uses four bytes. The complete character data occupies ten bytes.
These examples demonstrate why different languages and symbols can produce different file sizes even when the text appears short.
For multilingual applications, UTF-8 is often a practical choice because it supports a broad range of characters while storing basic English text efficiently.
8. The Difference Between Characters, Code Points, and Bytes
One common source of confusion is the assumption that a character always equals one byte. In reality, several related concepts must be distinguished.
A character is a unit of text as understood by a reader. For example, the letter A is a character.
A Unicode code point is a numerical value assigned to a Unicode character or text element. It is commonly written in a form such as U+0041 for A.
A byte is a unit used to store encoded data. An encoding format determines how a code point is represented as bytes.
These concepts do not always correspond one-to-one.
For example, the visible character é can be represented by the single Unicode code point U+00E9. It can also be represented by the sequence U+0065 (e) followed by U+0301, a combining acute accent.
In UTF-8, the first representation requires two bytes. The second representation requires three bytes: one for e and two for the combining accent.
Both sequences can display as the same visible character, depending on the software and rendering system. Yet they occupy different amounts of storage.
This explains why counting visible characters alone is not always enough to determine the exact size of a text file.
9. Other Factors That Affect Text File Size
Character encoding is a major factor in text storage, but it is not the only one.
File headers and byte-order marks
Some files include a byte-order mark (BOM) or other metadata. A BOM can help identify an encoding or indicate byte order in certain formats. Its presence adds bytes to the file, although UTF-8 does not require a BOM.
Line endings
Text files may use different line-ending conventions. For example, some systems use a line feed (LF), while others use a carriage return followed by a line feed (CRLF). Different conventions can change the total file size.
Spaces and punctuation
Spaces, tabs, punctuation marks, and newline characters also require storage. In UTF-8, many common English punctuation marks and spaces occupy one byte each.
Formatting and metadata
A plain text file generally contains text data, but documents such as word-processing files may also contain formatting instructions, styles, embedded images, and metadata. Their overall sizes cannot be calculated from character encoding alone.
Compression
Text can be compressed to reduce storage requirements. Compression algorithms identify repeated patterns and represent them more efficiently. The final compressed size depends on the content, encoding, and compression method.
For these reasons, the size of an entire file may differ from the number of bytes required for its characters alone.
10. How Character Encoding Affects Databases and Websites
Character encoding matters in many areas of computing.
Databases
Databases store names, messages, descriptions, and other text fields. The encoding and database storage format influence how much space text values require. Database systems may also reserve space for fields or use additional structures, so actual storage can be more complex than the encoded text size.
Choosing a suitable character set is particularly important when a database contains multiple languages.
Websites
Websites frequently use UTF-8 to represent text in HTML pages. Because UTF-8 supports a broad range of languages, it helps websites display international content consistently.
The size of HTML documents can influence how much data must be transferred to visitors. However, network transfer size may be smaller than the uncompressed file size when HTTP compression is used.
Programming
Programming languages and software libraries often provide functions for measuring text length and encoded byte length. These values may be different.
For example, a string containing an emoji may count as one Unicode code point in one operation but two UTF-16 code units in another. Its UTF-8 representation may occupy four bytes.
Developers must understand these differences when handling file sizes, memory limits, database fields, and network messages.
Data transmission
Text transmitted across a network is converted into bytes. The encoding affects the number of bytes that must be transmitted, which can influence bandwidth usage and transmission time.
For large datasets or high-volume messaging systems, even small differences in the average number of bytes per character can become significant.
11. How to Calculate the Storage Required for Text
A basic estimate can be made using the number of encoded bytes required by the characters.
For fixed-width encoding, the calculation is relatively straightforward when every character is represented using the same number of bytes.
For example, if a text contains 500 UTF-32 code points, each represented by four bytes:
500 × 4 = 2,000 bytes
For variable-width encoding such as UTF-8, the number of bytes must be calculated from the actual characters.
A simplified general formula is:
Encoded text size = Sum of the bytes used by each encoded character or code point
For a string containing 100 basic English characters in UTF-8:
100 × 1 = 100 bytes
For a string containing 100 characters that each require three bytes in UTF-8:
100 × 3 = 300 bytes
The second calculation applies only when each of those 100 items corresponds to a single code point that encodes to three bytes. Some visible characters consist of multiple code points, so a real calculation must account for the actual sequence.
These calculations estimate the encoded text data only. File headers, line endings, metadata, formatting, and other content may increase the total file size.
12. Which Character Encoding Is Best for Saving Storage?
There is no universal answer for every situation, because the best encoding depends on the text and the requirements of the software.
UTF-8 is a widely used default for websites, text files, and data exchange. It stores basic English characters efficiently and supports international text.
UTF-16 may be suitable in systems that use UTF-16 internally or where its characteristics fit the application’s requirements. It can use more space than UTF-8 for English-heavy content but may represent some other text efficiently.
UTF-32 provides a fixed-width representation for Unicode code points, which can simplify certain processing tasks. However, it generally requires more storage for text that could be represented using fewer bytes in UTF-8 or UTF-16.
In practice, developers should choose an encoding that supports the required languages, works correctly with the software, and meets storage and compatibility requirements. Using an encoding that cannot represent the required characters can lead to errors, missing characters, or corrupted text.
Conclusion
Character encoding affects the amount of storage required for text because different encoding systems represent characters using different numbers of bytes. ASCII-compatible English text typically uses one byte per character in UTF-8, while many international characters require two or three bytes and some supplementary characters require four. UTF-16 commonly uses two or four bytes per Unicode code point representation, while UTF-32 uses four bytes per code point.
Therefore, the number of visible characters alone cannot always determine a text file’s size. The actual characters, their Unicode representations, the encoding format, and additional file information all contribute to the final result. Understanding these differences helps developers and computer users estimate storage requirements, design multilingual applications, optimize data transmission, and handle text correctly across different systems.
FAQs
1. What is character encoding in computer science?
Character encoding is a system that converts text characters into numerical representations that computers can store and process. Computers work with binary data, so letters, numbers, punctuation marks, and symbols must be represented using bits and bytes. Common encoding formats include ASCII, UTF-8, UTF-16, and UTF-32. Each format follows specific rules for representing characters. These rules determine how many bytes are required to store particular text. Understanding character encoding is important for creating text files, developing websites, managing databases, and transmitting information accurately between different computer systems.
2. Why does character encoding affect text file size?
Character encoding affects text file size because different encoding formats use different numbers of bytes to represent the same character. For example, the English letter A requires one byte in UTF-8, two bytes in UTF-16, and four bytes in UTF-32. When a document contains thousands of characters, these differences can significantly influence its storage requirements. The result also depends on the characters being used. English-heavy text may occupy less space in UTF-8 than UTF-16 or UTF-32, while multilingual text can have different storage requirements depending on its character composition and encoding format.
3. How many bytes does one character require in UTF-8?
UTF-8 uses between one and four bytes to represent a Unicode code point. Basic English letters, digits, and many common punctuation marks generally require one byte. Many accented Latin characters require two bytes, while numerous characters from writing systems such as Devanagari require three bytes. Supplementary Unicode characters, including many emojis, require four bytes. However, a visible character does not always correspond to a single Unicode code point. Some visible characters consist of multiple code points, so their combined encoded representation can require additional bytes. Therefore, the actual storage requirement depends on the text.
4. What is the difference between ASCII and UTF-8?
ASCII is an early character encoding standard that defines 128 character values, including English letters, digits, punctuation marks, and control characters. Standard ASCII uses seven bits per value, although its characters are commonly stored in eight-bit bytes. UTF-8 is a Unicode encoding format that supports characters from many languages and writing systems. It is also compatible with ASCII: standard ASCII characters use the same byte values in UTF-8. However, UTF-8 can represent a much broader range of characters, using one to four bytes per Unicode code point. This makes UTF-8 suitable for multilingual websites and applications.
5. Why do emojis require more storage than English letters?
Many emojis require more storage because their Unicode code points fall outside the range represented by a single byte in UTF-8. For example, the emoji 😀 requires four bytes in UTF-8, whereas the English letter A requires only one byte. Some displayed emojis also contain multiple Unicode code points, such as a base emoji combined with a skin-tone modifier or another character. Consequently, certain emoji sequences require more bytes than individual emojis. When messages contain numerous emojis, their encoded text can occupy considerably more storage than an equally short message containing only basic English characters.
6. Which character encoding uses the least storage space?
No encoding uses the least storage for every possible text. UTF-8 is often space-efficient for English text because basic English characters require one byte each. UTF-16 commonly uses two bytes for basic English characters, while UTF-32 uses four bytes per Unicode code point. However, characters from other writing systems can require multiple bytes in UTF-8, so comparisons depend on the actual content. UTF-16 can be more competitive for certain character distributions, although UTF-8 remains a widely used choice for web content and multilingual data. The best encoding should balance storage efficiency, compatibility, and character support.
7. How can character encoding be used to calculate text storage?
Text storage can be estimated by adding the number of bytes required to encode each character or code point. For example, a string containing 100 basic English characters requires approximately 100 bytes when encoded in UTF-8, assuming no additional file information is included. If 100 code points each require three bytes, their encoded data occupies 300 bytes. UTF-32 uses four bytes per Unicode code point, so 100 code points require 400 bytes. These calculations estimate encoded text data only. Headers, line endings, metadata, and other file contents may increase the final file size.
8. What is the difference between a character, a code point, and a byte?
A character is a unit of text that people recognize, such as A or é. A Unicode code point is a numerical value assigned to a Unicode character or text element, written in a form such as U+0041. A byte is a unit of digital storage consisting of eight bits. Encoding formats determine how Unicode code points are represented using bytes. These concepts do not always correspond one-to-one. For example, the visible character é can be represented by one Unicode code point or by the letter e followed by a combining accent. These representations can require different numbers of bytes.
9. Does changing character encoding change the meaning of text?
Changing character encoding does not necessarily change the meaning of text, provided the text is correctly decoded and re-encoded. For example, converting a document from UTF-8 to UTF-16 can preserve its characters while changing the number of bytes required to store them. However, if software interprets bytes using the wrong encoding, characters may appear incorrectly or become unreadable. This problem is sometimes called character encoding corruption or mojibake. To prevent it, applications should identify and handle encodings consistently. Correct encoding is especially important for websites, databases, multilingual documents, and communication between different computer systems.
10. Why is UTF-8 widely used for websites and applications?
UTF-8 is widely used because it supports characters from many languages while maintaining compatibility with ASCII. Basic English text can be stored efficiently, and international characters, mathematical symbols, and emojis can also be represented. This makes UTF-8 suitable for websites, APIs, databases, and text files used across different platforms. It can also reduce storage and transmission requirements for English-heavy content compared with fixed-width alternatives such as UTF-32. However, storage efficiency is only one consideration. Correct implementation, consistent encoding, and compatibility with the software environment are equally important for displaying and processing text accurately.