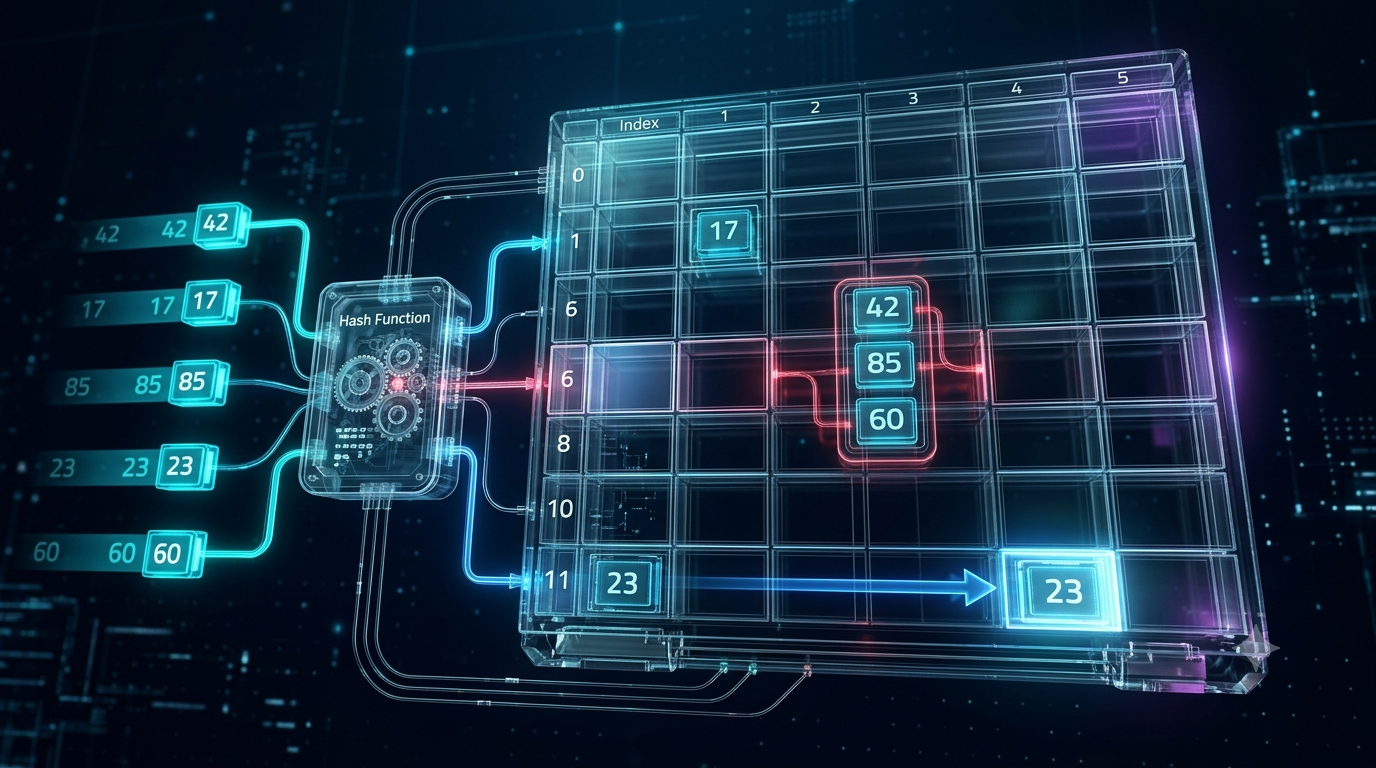
Hashing is an important concept in computer science that helps computers store, organize, and retrieve data efficiently. It is widely used in databases, programming languages, search systems, password storage, caching, and many other applications. When a program needs to find a particular value among thousands or millions of records, searching every record one by one can be slow. Hashing provides a way to locate data quickly by converting a key into a numerical value that determines where the data should be stored.
A hash table is a data structure that uses hashing to organize information into locations called slots or buckets. A hash function calculates an index from a given key, allowing a program to access the corresponding data efficiently. Although the basic idea is simple, practical hashing involves several important concepts, including hash functions, table size, collisions, load factor, and collision resolution. Understanding these concepts provides a strong foundation for learning more advanced computer science topics.
1. What Is Hashing?
Hashing is the process of transforming an input, such as a number, word, or data record, into a value using a mathematical or computational function called a hash function.
The input is commonly called a key, while the calculated result is called a hash value or hash code. In a hash table, the hash value is used to determine the location where the associated data should be stored.
For example, suppose a computer program needs to store student records using their identification numbers. Instead of checking every record to find a particular student, the program can apply a hash function to the identification number and calculate the location of the record.
Consider this simple hash function:
h(k) = k mod 10
Here:
h(k) represents the hash function.
k represents the input key.
mod represents the modulo operation, which returns the remainder after division.
If the key is 123, the calculation is:
123 mod 10 = 3
Therefore, the calculated hash index is 3.
This means that the program can use index 3 as the intended location for the key in a hash table with ten slots.
Hashing does not guarantee that every key receives a unique index. Different keys may produce the same index, creating a situation called a collision.
2. What Is a Hash Function?
A hash function is an algorithm that converts a key into a hash value. In a hash table, this value is usually mapped to a valid table index.
A good hash function should be fast to calculate and distribute keys reasonably evenly across the available table locations. A poor hash function may send too many keys to the same locations, making data retrieval slower.
For example, consider the following function:
h(k) = k mod 7
Suppose the keys are 10, 18, 25, 32, and 41.
Their hash values are:
h(10) = 10 mod 7 = 3
h(18) = 18 mod 7 = 4
h(25) = 25 mod 7 = 4
h(32) = 32 mod 7 = 4
h(41) = 41 mod 7 = 6
The resulting indexes are 3, 4, 4, 4, and 6.
Notice that three different keys produce index 4. This demonstrates why selecting an appropriate hash function matters.
Common properties of a hash function used in a hash table include:
Deterministic output: The same key should produce the same hash result under the same conditions.
Efficiency: The function should be quick to calculate.
Good distribution: Keys should be spread across the table as evenly as practical.
Valid indexing: The final index must fall within the table’s available range.
A hash function designed for a hash table is not necessarily suitable for cryptographic purposes. Password hashing and digital security require additional properties and specialized algorithms.
3. What Is a Hash Table?
A hash table is a data structure that stores information using keys and their associated values. It uses a hash function to calculate where each key-value pair should be placed.
For example, imagine a hash table with seven slots, numbered from 0 to 6. The hash function is:
h(k) = k mod 7
If the program inserts the key 24, the calculation is:
24 mod 7 = 3
The key is therefore assigned to index 3, assuming that the slot is available or the collision-handling method permits insertion there.
A simplified representation of the table is:
| Index | Stored key |
|---|---|
| 0 | Empty |
| 1 | Empty |
| 2 | Empty |
| 3 | 24 |
| 4 | Empty |
| 5 | Empty |
| 6 | Empty |
A real hash table can store complete key-value pairs rather than keys alone. For example, a student ID might be the key, while the student’s name and other details form the associated value.
Hash tables are commonly used for dictionaries, maps, symbol tables, caches, and lookup systems.
4. Understanding the Modulo Operation in Hashing
The modulo operation is frequently used in simple hash functions because it converts an integer key into a remainder within a predictable range.
The notation is:
a mod m = remainder when a is divided by m
For example:
17 mod 5 = 2
24 mod 7 = 3
36 mod 10 = 6
50 mod 8 = 2
63 mod 9 = 0
When the hash table contains m slots numbered from 0 to m − 1, the function
h(k) = k mod m
produces an index in the range 0 to m − 1 for nonnegative integer keys and positive m.
For example, if the table contains 10 slots, its valid indexes are 0 through 9. Applying the modulo operation with 10 ensures that the resulting index falls within this range.
However, modulo hashing does not automatically produce a good distribution. If keys follow a particular numerical pattern, many may map to the same index. The quality of the distribution depends on the keys, the table size, and the hash function.
5. Calculating Hash Table Indexes
Calculating hash table indexes is one of the most fundamental hashing skills. The process involves identifying the key, selecting the hash function, substituting the key into the function, and calculating the resulting index.
Consider a hash table with 10 slots and the function:
h(k) = k mod 10
Calculate the indexes for the keys 14, 27, 35, 42, and 58.
The calculations are:
h(14) = 14 mod 10 = 4
h(27) = 27 mod 10 = 7
h(35) = 35 mod 10 = 5
h(42) = 42 mod 10 = 2
h(58) = 58 mod 10 = 8
The resulting table is:
| Key | Calculation | Hash index |
|---|---|---|
| 14 | 14 mod 10 | 4 |
| 27 | 27 mod 10 | 7 |
| 35 | 35 mod 10 | 5 |
| 42 | 42 mod 10 | 2 |
| 58 | 58 mod 10 | 8 |
All five keys receive different indexes, so no collision occurs in this example.
This does not mean the function will always avoid collisions. A different collection of keys could produce repeated indexes even when the same hash function is used.
6. What Is a Collision in Hashing?
A collision occurs when two or more different keys produce the same hash table index.
For example, consider the function:
h(k) = k mod 10
For the keys 21 and 31:
h(21) = 21 mod 10 = 1
h(31) = 31 mod 10 = 1
Both keys map to index 1. If the hash table has only one directly available slot at each index, the program needs a strategy for storing both keys.
Collisions are a normal part of hash table operation. They are unavoidable when a large or unlimited collection of possible keys must be mapped to a limited number of table positions.
The main goal is not to eliminate every possible collision. Instead, a good implementation distributes keys effectively and handles collisions without significantly reducing performance.
Two widely used collision-resolution techniques are separate chaining and open addressing.
7. Separate Chaining
Separate chaining is a collision-resolution method in which each table index can hold a collection of entries rather than just one entry. This collection is commonly implemented using a linked list, although other structures may also be used.
Consider a hash table with five slots and the function:
h(k) = k mod 5
Insert the keys 12, 17, 22, and 9.
The calculations are:
h(12) = 12 mod 5 = 2
h(17) = 17 mod 5 = 2
h(22) = 22 mod 5 = 2
h(9) = 9 mod 5 = 4
The keys 12, 17, and 22 all map to index 2. With separate chaining, they can be stored together in a collection associated with that index.
| Index | Stored keys |
|---|---|
| 0 | Empty |
| 1 | Empty |
| 2 | 12 → 17 → 22 |
| 3 | Empty |
| 4 | 9 |
The arrows represent a linked sequence of entries, not additional hash table indexes.
Advantages: Separate chaining is relatively straightforward to implement and can accommodate multiple entries at the same index.
Limitations: Additional memory may be needed for the collections, and long chains can make searching slower.
8. Open Addressing
Open addressing is another collision-resolution technique. Instead of storing multiple entries in a collection at one index, it searches for another available slot within the same table.
Several methods can be used to choose the next slot, including linear probing, quadratic probing, and double hashing.
Linear probing
Linear probing checks the next index when the calculated position is occupied. If that index is also occupied, it checks the following index until it finds an available location.
A common formula is:
hᵢ(k) = (h(k) + i) mod m
Here:
k is the key.
h(k) is the original hash index.
i is the probe number, beginning at 0.
m is the table size.
Suppose the table has 7 slots and the hash function is:
h(k) = k mod 7
Insert the keys 10, 17, and 24.
For key 10:
10 mod 7 = 3
The key is placed at index 3.
For key 17:
17 mod 7 = 3
Index 3 is occupied, so linear probing checks index 4. The key is placed at index 4.
For key 24:
24 mod 7 = 3
Index 3 is occupied, and index 4 is also occupied. The next index is 5, so the key is placed at index 5.
The final arrangement is:
| Index | Stored key |
|---|---|
| 0 | Empty |
| 1 | Empty |
| 2 | Empty |
| 3 | 10 |
| 4 | 17 |
| 5 | 24 |
| 6 | Empty |
Linear probing is easy to understand and implement, but it can create clusters of occupied slots. These clusters may increase the number of checks required for future insertions and searches.
9. Load Factor of a Hash Table
The load factor measures how full a hash table is. It is an important indicator of how efficiently the table may operate.
The formula is:
Load factor (α) = n / m
Where:
n is the number of stored entries.
m is the number of available table slots.
Suppose a hash table has 20 slots and contains 12 entries.
The calculation is:
α = 12 / 20 = 0.6
The load factor is 0.6, or 60%.
A higher load factor generally means more occupied positions and, depending on the collision-resolution method, a greater chance of collisions or longer searches.
For open addressing, performance can deteriorate significantly as the table becomes crowded. For separate chaining, a load factor greater than 1 is possible because each index can hold multiple entries.
A load factor alone does not determine performance. The quality of the hash function, the distribution of keys, the collision-resolution method, and the implementation also matter.
10. Average Time Complexity of Hash Tables
Time complexity describes how the time required by an algorithm changes as the amount of data increases.
Hash tables are popular because their basic operations can often be performed in constant expected time under suitable conditions.
| Operation | Average expected time | Worst-case time |
|---|---|---|
| Search | O(1) | O(n) |
| Insertion | O(1) | O(n) |
| Deletion | O(1) | O(n) |
Here, n represents the number of stored entries.
O(1) means constant time: the expected number of operations does not grow proportionally with the number of entries under the assumed conditions.
O(n) means linear time: the number of operations can grow in proportion to the number of entries.
These are general bounds for common implementations, not guarantees for every hash table operation. Resizing, unusually poor key distributions, long chains, and other implementation details can affect performance. Some implementations also use more sophisticated strategies to improve behavior.
11. Resizing and Rehashing
As a hash table receives more entries, its load factor increases. If the table becomes too crowded, the implementation may create a larger table and redistribute the stored entries.
This process is commonly called resizing and rehashing.
Suppose a table contains 8 slots and stores 6 entries.
Its load factor is:
α = 6 / 8 = 0.75
If the implementation decides that the table should grow, it might allocate 16 slots. The new load factor, assuming all six entries remain stored, becomes:
α = 6 / 16 = 0.375
The entries usually need to be inserted again using the hash function and the new table size. Simply copying each entry to its old index may not work because changing the table size can change the calculated indexes.
Resizing requires additional work when it occurs, but it helps maintain efficient performance as the data collection grows. The precise growth rule depends on the programming language and hash table implementation.
12. Hashing Strings and Text
Hashing is not limited to integer keys. Hash tables frequently use strings, such as names, usernames, product codes, and email addresses.
A string hash function processes the characters in a string to calculate a hash value. The resulting value is then mapped to an index within the table.
For example, a system might store the strings “Apple”, “Banana”, and “Orange” as keys in a dictionary. Each string is processed by the hash function to determine where its associated information should be stored.
Unlike the simple modulo examples involving integers, real string hash functions may use character codes, multiplication, bitwise operations, or other techniques to combine information from the characters.
The exact output depends on the chosen algorithm and its implementation. Therefore, it is not correct to assume that every programming language will produce the same hash value for a particular string.
A useful string hash function should distribute typical inputs well and should handle different string lengths and character patterns effectively.
13. Hashing Versus Cryptographic Hashing
Hashing has multiple applications, but not every hash function is designed for the same purpose.
Hash tables use hash functions to support efficient data organization and retrieval. Their main goals are speed and good distribution of keys.
Cryptographic hash functions serve security-related purposes. They are designed to provide properties such as resistance to finding inputs that produce a chosen hash output and resistance to finding different inputs with the same output.
Examples of cryptographic hash algorithms include SHA-256 and SHA-3.
Password storage requires special care. Applications should use established password-hashing algorithms, such as Argon2id, scrypt, or appropriately configured bcrypt or PBKDF2, rather than storing plain-text passwords or relying on a fast general-purpose hash function alone.
A hash table’s hash function is not automatically secure for password storage. Similarly, a cryptographic hash function is not always the most efficient choice for ordinary in-memory table lookups.
Understanding this distinction helps prevent confusion between data structure hashing and security-focused hashing.
14. Practical Applications of Hash Tables
Hash tables are used in many areas of computer science because they make key-based lookup convenient.
Dictionaries and maps: Programming languages use hash-based structures to associate keys with values, such as mapping a product code to its price.
Database indexing: Hash-based indexes can support efficient equality lookups when the database engine and query type are suitable for hashing.
Caching: Applications can use keys to locate previously calculated results or stored responses.
Duplicate detection: A program can use a hash-based set to check whether an item has already appeared in a collection.
Compiler design: Symbol tables can store information about variable names, functions, and other identifiers.
Counting and frequency analysis: Hash maps can count how often words, numbers, or other items appear in a dataset.
For example, a program that counts the frequency of words in an article can use each word as a key and its frequency as the associated value. When a word appears again, the program updates the existing count instead of searching through every previously encountered word.
These applications demonstrate why hashing is an essential concept in programming, algorithms, and data structure design.
15. Common Mistakes When Learning Hashing
Beginners often make a few predictable mistakes while studying hash tables.
Confusing the key with the hash index: The key is the original input, while the index is the calculated location in the table. A key of 123 may map to index 3, but the key itself remains 123.
Assuming collisions never occur: Different keys can produce the same index, even when the hash function is working as intended.
Ignoring table size: The table size affects the mapping of keys to indexes. Changing the size can require the stored entries to be redistributed.
Forgetting collision resolution: A complete hash table implementation must handle collisions using a suitable technique.
Assuming constant time is guaranteed: Hash tables commonly provide O(1) expected lookup time, but poor distributions and high load factors can make operations slower.
Confusing hashing with encryption: Hashing does not provide a method to recover the original input from a hash value. Encryption, in contrast, is designed to allow authorized decryption with the appropriate key.
Learning these distinctions makes it easier to solve hashing problems and understand how real implementations work.
Conclusion
Basic hashing and hash table calculations are fundamental topics in computer science. Hashing uses a function to transform a key into a value that helps determine where information should be stored. A hash table organizes key-value pairs around these calculated locations, allowing efficient searching, insertion, and deletion in many common situations.
The most important concepts include hash functions, modulo calculations, table indexes, collisions, separate chaining, open addressing, load factor, time complexity, and rehashing. Simple calculations such as h(k) = k mod m provide a useful starting point for understanding how keys map to table locations. More advanced concepts explain what happens when several keys map to the same location or when a table becomes crowded.
By practising index calculations and collision-resolution examples, learners can build a strong foundation for studying data structures, algorithms, databases, and programming. Hash tables are not perfect for every task, but their efficiency and flexibility make them one of the most widely used data structures in modern computing.
FAQs
1. What is hashing in computer science?
Hashing is a process that converts an input, such as a number, word, or data record, into a value using a function called a hash function. This value helps a computer determine where information should be stored or how it can be identified efficiently. Hashing is commonly used in hash tables, databases, caching systems, and programming applications. For example, a hash function can convert a student identification number into an index in a table. This allows the program to locate the associated record without searching every entry individually, making data retrieval faster in many situations.
2. What is a hash table?
A hash table is a data structure that stores information as key-value pairs and uses a hash function to determine where each pair should be placed. The key identifies the information, while the value contains the associated data. For example, a student ID can serve as a key, and the student’s name can be its value. Hash tables are designed to support efficient insertion, searching, and deletion. However, different keys may produce the same index, creating collisions. Techniques such as separate chaining and open addressing help manage these collisions and maintain efficient performance.
3. What is a hash function, and how does it work?
A hash function is an algorithm that converts a key into a hash value, which can be used to determine its location in a hash table. A simple example is h(k) = k mod 10, where k represents the key and mod returns the remainder after division. If the key is 27, the calculation is 27 mod 10 = 7. Therefore, the key maps to index 7 in a table with ten slots. A good hash function should be efficient, produce consistent results for the same key, and distribute keys reasonably evenly across available locations.
4. How do you calculate a hash table index?
To calculate a hash table index, first identify the key and the hash function. Then substitute the key into the function and perform the required calculation. For example, suppose a hash table contains eight slots and uses h(k) = k mod 8. If the key is 29, calculate 29 mod 8. Since 29 divided by 8 leaves a remainder of 5, the hash index is 5. The table’s indexes range from 0 to 7. This method provides a straightforward way to map nonnegative integer keys to valid table positions using the modulo operation.
5. What is a collision in hashing?
A collision occurs when two or more different keys produce the same hash table index. For example, consider the function h(k) = k mod 10. The keys 15 and 25 both produce index 5 because 15 mod 10 = 5 and 25 mod 10 = 5. Collisions are normal because a hash table has a limited number of positions, while the possible keys may be extremely numerous. A hash table must therefore use a collision-resolution technique. Common methods include separate chaining, which stores multiple entries at one index, and open addressing, which searches for another available slot.
6. What is the difference between separate chaining and open addressing?
Separate chaining and open addressing are two techniques used to handle collisions in hash tables. Separate chaining allows each index to maintain a collection of entries, often using a linked list. When several keys map to the same index, they are stored in that collection. Open addressing stores entries directly within the table and searches for another available slot when a collision occurs. Linear probing is one example of open addressing. Separate chaining may require additional memory for its collections, while open addressing can become less efficient as the table fills. The best method depends on the implementation and application requirements.
7. What is the load factor of a hash table?
The load factor measures how many entries a hash table stores relative to its number of available slots. It is calculated using the formula α = n / m, where n represents the number of stored entries and m represents the table capacity. For example, if a table has 20 slots and stores 10 entries, its load factor is 10 / 20 = 0.5, or 50%. A higher load factor can increase collisions and slow down operations, especially in open addressing. Many implementations resize the table when the load factor reaches a chosen threshold to maintain efficient performance.
8. What is the average time complexity of hash table operations?
Hash tables commonly provide O(1) expected time complexity for searching, inserting, and deleting entries when the hash function distributes keys well and the table is appropriately managed. O(1) means that the expected operation time remains approximately constant as the number of entries increases. However, these operations can take O(n) time in the worst case, where n is the number of entries. This can happen when many keys collide and must be checked sequentially. Actual performance depends on factors such as the hash function, load factor, collision-resolution method, and implementation. Constant-time performance is expected, not guaranteed.
9. What is rehashing in a hash table?
Rehashing is the process of recalculating the positions of stored entries, commonly when a hash table grows or changes its capacity. As more entries are inserted, the table may become crowded, increasing the likelihood of collisions and slower operations. To address this problem, the implementation can create a larger table and insert the existing entries again using the updated table size. For example, a table might grow from eight slots to sixteen slots. Since the hash calculation may depend on the table size, existing keys can receive different indexes. Rehashing requires additional work but helps maintain efficient performance as the collection grows.
10. What are the main applications of hashing and hash tables?
Hashing and hash tables are used in many computer science applications that require efficient data access. Programming languages use hash-based dictionaries and maps to associate keys with values. Databases can use hash-based indexes for suitable equality searches, while caching systems use keys to retrieve previously stored results. Hash tables also support duplicate detection, word-frequency counting, compiler symbol tables, and data lookup systems. Cryptographic hashing serves different purposes, including digital signatures and password-storage systems when appropriate algorithms are used. However, ordinary hash table functions are not necessarily secure for cryptographic applications. Choosing the correct hashing technique depends on the problem being solved.