Hash tables are widely used in computer science to store and retrieve data efficiently. They are found in databases, programming languages, caching systems, dictionaries, and many other applications. A hash table uses a hash function to convert a key into an index where the corresponding value can be stored. However, the performance of a hash table depends on more than just its hash function. One important factor is the load factor, which describes how full the hash table is.
The load factor helps programmers understand how efficiently a hash table is being used and when it may need to increase its capacity. A high load factor can lead to more collisions and slower operations, while a low load factor generally provides more space for new entries. Learning the load factor formula makes it easier to understand hash table performance, resizing, and memory usage. In this article, we will explore the load factor formula, its components, practical examples, and its importance in computer science.
What Is the Load Factor in a Hash Table?
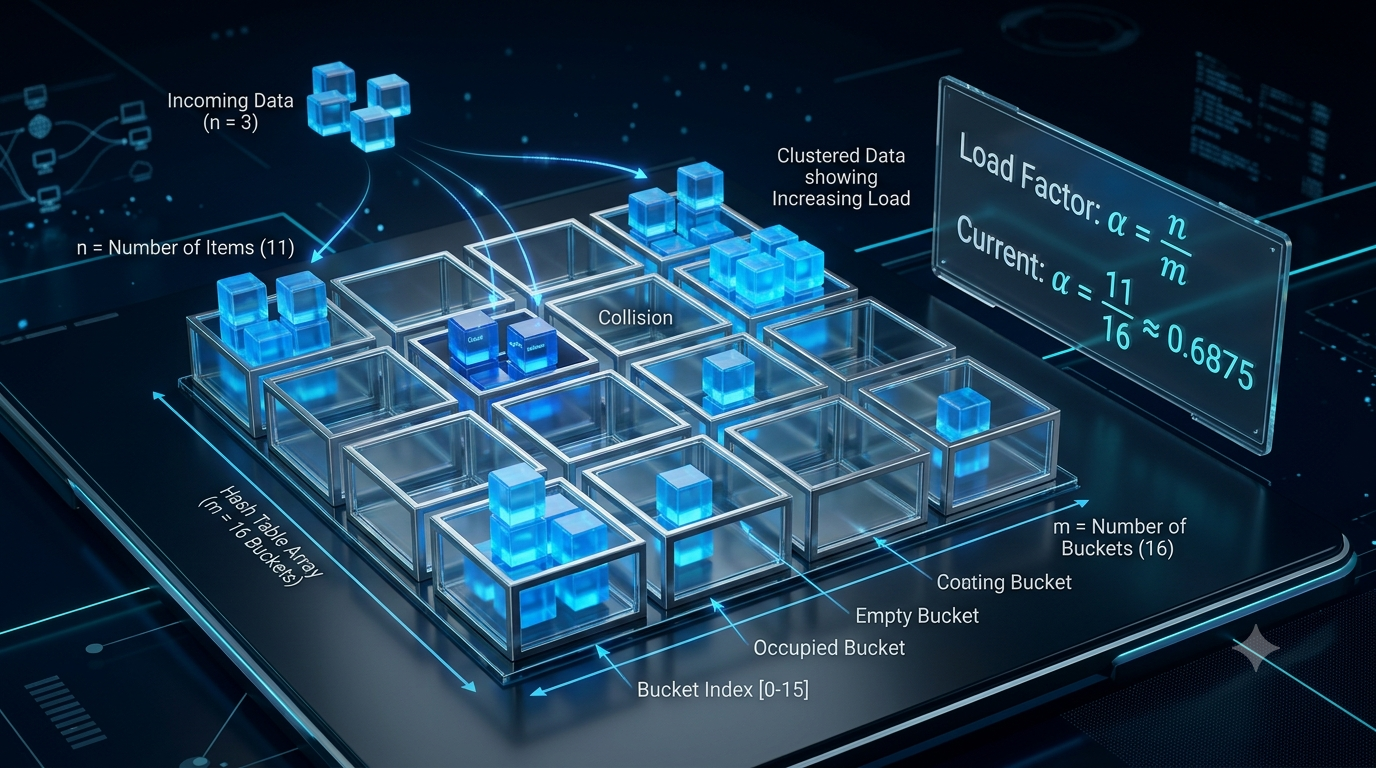
The load factor is a numerical value that represents the ratio between the number of entries stored in a hash table and the total number of available slots, or buckets, in that table.
In simple terms, it tells us how much of the hash table’s capacity is being used.
For example, imagine a hash table that has 10 buckets and contains 5 entries. Half of its available bucket capacity is occupied, so its load factor is 0.5.
The load factor is important because hash tables work most efficiently when their entries are distributed appropriately across the available buckets. As more entries are added, collisions may become more frequent, depending on the collision-handling method used.
A hash table can have a load factor below 1, equal to 1, or even greater than 1. The possible values depend on its implementation. In open addressing, the load factor generally cannot exceed 1 because each slot can hold only one entry. In separate chaining, multiple entries can be stored in the same bucket, allowing the load factor to exceed 1.
Load Factor Formula
The standard formula for calculating the load factor of a hash table is:
Load Factor = Number of Stored Entries ÷ Total Number of Buckets
It can also be written mathematically as:
α = n / m
Where:
α (alpha) = Load factor of the hash table
n = Number of entries stored in the hash table
m = Total number of buckets in the hash table
The Greek letter alpha is commonly used to represent the load factor in discussions of hash table performance.
Understanding the Formula
The formula divides the number of stored entries by the total number of buckets.
If the hash table contains 20 entries and has 40 buckets, its load factor is:
α = 20 / 40 = 0.5
This means the table contains an average of 0.5 entries per bucket.
A load factor of 0.5 does not necessarily mean that exactly half of the buckets are occupied. Multiple entries may be stored in the same bucket when separate chaining is used. The value represents an average ratio, not always the exact percentage of occupied buckets.
Components of the Load Factor Formula
To use the formula correctly, it is helpful to understand its two main components.
1. Number of Stored Entries (n)
The number of stored entries represents the total number of key-value pairs currently held in the hash table.
For example, suppose a hash table stores the following student records:
Student ID 101: Rahul
Student ID 102: Priya
Student ID 103: Amit
Student ID 104: Neha
The table contains four entries, so n = 4.
When a new key-value pair is inserted, the number of entries usually increases by one. When an existing entry is removed, the number of stored entries decreases by one.
Some implementations distinguish between active entries, deleted markers, and unused slots. In such cases, the exact counting method depends on how the hash table manages deleted entries and vacant positions.
2. Total Number of Buckets (m)
The total number of buckets represents the hash table’s current capacity in terms of the number of positions available for storing or organizing entries.
For example, if a hash table is created with 16 buckets, then m = 16.
The number of buckets may remain constant for a period of time. However, many hash table implementations increase the capacity when the load factor exceeds a chosen threshold.
Increasing the number of buckets can reduce the average number of entries associated with each bucket and help maintain efficient performance.
Examples of Calculating the Load Factor
Let’s examine several examples to understand how the formula works in different situations.
Example 1: A Hash Table with a Low Load Factor
Suppose a hash table contains 10 entries and has 50 buckets.
Given:
Number of entries: n = 10
Number of buckets: m = 50
Using the formula:
Load factor = n / m
Load factor = 10 / 50
Load factor = 0.2
The load factor is 0.2, meaning the table has an average of 0.2 entries per bucket.
This relatively low value indicates that the table has considerable capacity available. However, it does not guarantee that every entry occupies a separate bucket or that all operations will be equally fast.
Example 2: A Hash Table with a Moderate Load Factor
Suppose a hash table contains 30 entries and has 40 buckets.
Given:
Number of entries: n = 30
Number of buckets: m = 40
Calculation:
Load factor = 30 / 40
Load factor = 0.75
The load factor is 0.75, which means there are 0.75 entries per bucket on average.
This value may be acceptable for many hash table implementations. For example, some implementations using open addressing resize the table when the load factor reaches approximately 0.7 or 0.75. The appropriate threshold depends on the implementation and its performance goals.
Example 3: A Hash Table with a Load Factor Greater Than 1
Consider a hash table that contains 60 entries and has 40 buckets.
Given:
Number of entries: n = 60
Number of buckets: m = 40
Calculation:
Load factor = 60 / 40
Load factor = 1.5
The load factor is 1.5, meaning the table contains an average of 1.5 entries per bucket.
This situation is possible when the hash table uses separate chaining, where each bucket can hold multiple entries. It is generally not possible in a conventional open-addressing table where every entry must occupy a unique slot.
A load factor above 1 does not automatically mean the hash table is malfunctioning. It indicates that, on average, more than one entry is associated with each bucket.
Example 4: Finding the Number of Entries
Sometimes, the load factor and the number of buckets are known, but the number of entries is not.
Suppose a hash table has 80 buckets and a load factor of 0.5.
The formula is:
α = n / m
Rearranging the formula:
n = α × m
Substituting the values:
n = 0.5 × 80
Number of entries = 40
Therefore, the hash table contains 40 entries.
This rearranged formula is useful when estimating how many entries a hash table can hold before reaching a particular load factor.
Example 5: Finding the Required Number of Buckets
Suppose a hash table contains 120 entries, and the target load factor is 0.75.
To determine the required number of buckets, rearrange the formula:
α = n / m
m = n / α
Substituting the values:
m = 120 / 0.75
Required number of buckets = 160
Therefore, 160 buckets are needed to maintain a load factor of 0.75 with 120 entries.
In practical implementations, the actual capacity may be rounded up to a supported size, such as a power of two or another capacity selected by the hash table’s resizing policy.
What Is a Good Load Factor?
There is no single ideal load factor for every hash table. The appropriate value depends on the collision-handling method, memory limitations, expected workload, and implementation.
Low Load Factor
A low load factor means the number of entries is small compared with the number of buckets.
For example, a load factor of 0.25 indicates an average of 0.25 entries per bucket.
Advantages of a low load factor include:
More available capacity for future insertions.
Generally fewer collisions in a well-distributed hash table.
Potentially faster operations in implementations that are sensitive to collisions.
However, a low load factor may waste memory because many buckets remain unused. It also does not prevent collisions if the hash function distributes keys poorly.
Moderate Load Factor
A moderate load factor balances memory usage and performance.
For example, a load factor of 0.5 means there are, on average, half as many entries as buckets.
This can provide a reasonable balance between available space and efficient access. Nevertheless, the actual performance depends on the quality of the hash function and the collision-resolution technique.
High Load Factor
A high load factor means that the table contains many entries relative to its capacity.
For separate chaining, this generally increases the average number of entries in each bucket. For open addressing, it reduces the number of empty slots available for probing.
A high load factor can cause:
More work during collision resolution.
Longer search or insertion sequences.
Reduced performance for some operations.
A greater likelihood that the table will need resizing.
A high load factor is not always a problem, especially in a well-designed implementation using separate chaining. However, it must be considered when optimizing performance.
Load Factor and Hash Table Collisions
A collision occurs when two or more different keys map to the same bucket or slot.
For example, suppose a hash table uses a hash function that maps the keys 12 and 22 to the same bucket. Both keys compete for the same location, creating a collision.
The load factor helps describe how densely entries are stored, but it does not directly measure the number of collisions.
When the load factor increases, collisions often become more likely, assuming the hash function distributes keys reasonably well. However, poor hash functions can cause frequent collisions even when the load factor is low.
Hash tables commonly use two major collision-resolution methods.
Separate Chaining
In separate chaining, each bucket can hold a collection of entries. This collection might be a linked list or another data structure.
For example, if a table has 10 buckets and 20 entries, the load factor is:
α = 20 / 10 = 2
A load factor of 2 means that there are two entries per bucket on average. Some buckets may contain no entries, while others may contain several.
Separate chaining can accommodate load factors greater than 1, although search performance may decline as the average chain length increases.
Open Addressing
In open addressing, all entries are stored directly within the hash table’s array. When a collision occurs, the algorithm searches for another available slot using a probing strategy.
Common approaches include:
Linear probing
Quadratic probing
Double hashing
In conventional open addressing, the load factor must remain below 1 because each slot can store only one entry. As the load factor approaches 1, empty slots become scarce, and insertions or unsuccessful searches may require many probes.
For this reason, open-addressing implementations often resize the table before it becomes nearly full.
Load Factor and Hash Table Resizing
Resizing is the process of changing a hash table’s capacity to maintain acceptable performance as the number of entries changes.
Many implementations use a maximum load factor, also called a load-factor threshold. When the current load factor exceeds this threshold, the table may increase its capacity.
For example, suppose a hash table has:
16 buckets
12 stored entries
A maximum load factor of 0.75
Its current load factor is:
α = 12 / 16 = 0.75
If another entry is inserted, the load factor would become:
α = 13 / 16 = 0.8125
If the implementation triggers resizing when the load factor exceeds 0.75, the table may increase its capacity before or during that insertion.
After resizing, the entries are commonly redistributed across the new bucket array. This process is often called rehashing, although implementations may reuse stored hash information rather than recomputing every hash value from scratch.
Resizing takes time and may temporarily require additional memory. However, it can improve the efficiency of future operations by reducing the load factor.
The exact threshold and resizing strategy depend on the programming language and hash table implementation.
Load Factor Formula in Programming
Programmers can calculate the load factor by dividing the number of stored entries by the current capacity.
For example, consider this Python code:
def calculate_load_factor(size, capacity):
Output:
Load factor: 0.75The function accepts the number of entries and the capacity of the table, checks that the capacity is positive, and returns their ratio.
This example demonstrates the mathematical calculation. It does not inspect or resize an actual Python dictionary. In real applications, a hash table’s internal capacity may not be publicly accessible, so programmers must use the features provided by their chosen language or library.
Applications of the Load Factor Formula
The load factor is useful in many areas of computer science.
1. Database Indexing
Hash-based indexes can use hashing to locate records efficiently. Understanding the load factor helps developers evaluate how densely entries are stored and whether additional capacity may be needed.
2. Caching Systems
Caches often use hash tables to locate stored values quickly. Monitoring the load factor can help guide capacity management and performance optimization.
3. Programming Language Dictionaries
Many programming languages provide dictionary, map, or hash map data structures. These structures use hashing internally, and their implementations may monitor the load factor when deciding whether to resize.
4. Symbol Tables
Compilers use symbol tables to manage information about variables, functions, and other identifiers. Hash tables can provide efficient access to these records, making load-factor management relevant to their performance.
5. Data Processing
Applications that process large numbers of unique records may rely on hash tables for grouping, counting, deduplication, and lookup operations. The load factor helps developers understand the relationship between the number of entries and allocated capacity.
Advantages of Monitoring the Load Factor
Monitoring the load factor offers several benefits.
First, it helps developers estimate how full a hash table is relative to its bucket capacity. This information can support decisions about when to resize the table.
Second, it helps balance memory consumption and operation speed. Allocating too many buckets can waste memory, while allocating too few may increase collision-resolution costs.
Third, it supports performance analysis. When a hash table becomes slower as more entries are added, the load factor is one of the useful measurements to examine alongside the hash function and collision-resolution strategy.
Finally, it helps developers understand why different hash table implementations use different resizing thresholds. A threshold that works well for one implementation may not be ideal for another.
Limitations of the Load Factor Formula
Although the load factor is useful, it cannot explain every aspect of hash table performance.
The formula measures the ratio of entries to buckets, but it does not reveal how evenly the entries are distributed.
For example, two hash tables may have the same load factor of 0.5. In one table, entries may be distributed evenly. In the other, many entries may collide in a few buckets because of a poor hash function.
Both tables have the same load factor, but their search performance can differ significantly.
The load factor also does not directly measure memory overhead, the cost of computing hash values, or the number of probes required by open addressing.
Therefore, developers should consider the load factor together with the hash function, collision-resolution method, resizing policy, and actual performance measurements.
Conclusion
The load factor formula is a fundamental concept for understanding how hash tables manage stored data and available capacity. It is calculated by dividing the number of stored entries by the total number of buckets, using the formula α = n / m. This simple ratio helps developers evaluate how densely a hash table is populated and understand when resizing may be beneficial.
A low load factor generally provides more available capacity but may use memory inefficiently. A high load factor can increase collision-resolution costs, particularly in open-addressing implementations. The ideal value depends on the hash table’s design and the application’s requirements.
By understanding the load factor formula, its calculation, and its relationship with collisions and resizing, learners can build a stronger foundation in data structures and algorithm analysis.
Key Takeaways
The load factor measures the ratio of stored entries to available buckets.
The formula is α = n / m.
A low load factor means fewer entries per bucket on average.
A high load factor may increase collision-resolution costs.
Separate chaining can support a load factor greater than 1.
Conventional open addressing requires the load factor to remain below 1.
Resizing can help maintain performance as a hash table grows.
The load factor alone does not determine hash table performance; the hash function and collision-resolution strategy also matter.
FAQs
1. What Is the Load Factor in a Hash Table?
The load factor in a hash table is a measure of how many entries are stored relative to the total number of available buckets. It helps developers understand how densely the table is populated. The load factor is calculated by dividing the number of stored entries by the total number of buckets. A low load factor generally means more available capacity, while a high load factor indicates that entries are using a larger proportion of the table’s capacity. This measurement is important for understanding collision behavior, memory usage, and when a hash table might need resizing.
2. What Is the Formula for Calculating the Load Factor?
The standard formula for calculating the load factor of a hash table is:
Load Factor = Number of Stored Entries ÷ Total Number of Buckets
Mathematically, it is represented as α = n / m, where α represents the load factor, n is the number of stored entries, and m is the total number of buckets. For example, if a hash table contains 20 entries and has 40 buckets, its load factor is 20 / 40 = 0.5. This means there are 0.5 entries per bucket on average. The formula helps estimate table utilization and supports capacity management decisions.
3. What Is Considered a Good Load Factor for a Hash Table?
A good load factor depends on the hash table’s implementation and performance requirements. A value around 0.5 may provide a balance between available space and memory usage. Some implementations use thresholds around 0.7 or 0.75, particularly when managing open-addressing tables. Separate-chaining implementations may allow higher load factors because multiple entries can occupy the same bucket. However, a higher load factor can increase search costs. Developers should consider the collision-resolution method, memory constraints, and expected workload rather than assuming that one particular value is ideal for every hash table.
4. Can the Load Factor of a Hash Table Be Greater Than 1?
Yes, a hash table’s load factor can be greater than 1 when it uses separate chaining. In this method, each bucket can store multiple entries, so the number of entries may exceed the number of buckets. For example, a table containing 60 entries and 40 buckets has a load factor of 60 / 40 = 1.5. This means there are 1.5 entries per bucket on average. However, conventional open-addressing hash tables generally require a load factor below 1 because each entry occupies a separate slot in the table.
5. How Does the Load Factor Affect Hash Table Performance?
The load factor can significantly influence hash table performance because it describes how densely entries are stored. As the load factor increases, collisions may become more frequent, depending on the hash function and collision-resolution method. In separate chaining, higher values can produce longer bucket chains. In open addressing, fewer empty slots remain available, potentially increasing the number of probes required for searches and insertions. A lower load factor can improve performance in these situations but may consume more memory. The actual performance also depends on the quality of the hash function and the distribution of keys.
6. What Is the Relationship Between Load Factor and Hash Table Collisions?
The load factor and collisions are related, but they are not the same thing. The load factor measures the ratio of stored entries to available buckets, while a collision occurs when different keys map to the same bucket or slot. Increasing the load factor generally increases the likelihood of collisions when keys are distributed reasonably well. However, a poorly designed hash function can create many collisions even when the load factor is low. Therefore, developers should consider both the load factor and the quality of the hash function when evaluating hash table performance and deciding whether improvements are necessary.
7. When Should a Hash Table Be Resized?
A hash table is commonly resized when its load factor exceeds a predefined threshold. Resizing increases the table’s capacity to accommodate more entries and may reduce collision-related performance costs. For example, if a hash table has 16 buckets and 12 entries, its load factor is 12 / 16 = 0.75. If its maximum threshold is 0.75, inserting another entry may trigger resizing, depending on the implementation’s policy. After resizing, entries are typically redistributed across the new bucket array. The exact threshold and resizing procedure vary among programming languages and hash table implementations.
8. How Can You Calculate the Number of Buckets Using the Load Factor?
The number of buckets can be calculated when the number of stored entries and the target load factor are known. Rearrange the standard formula, α = n / m, to obtain m = n / α. For example, suppose a hash table contains 100 entries and the target load factor is 0.5. The required number of buckets is 100 / 0.5 = 200. Therefore, 200 buckets are needed to achieve the target load factor. In actual implementations, the capacity may be rounded to a supported size according to the hash table’s resizing policy.
9. What Is the Difference Between Load Factor and Table Capacity?
Load factor and table capacity describe different aspects of a hash table. Capacity refers to the number of buckets or slots available in the table. The load factor represents the ratio of stored entries to that capacity. For example, a hash table with 25 entries and 50 buckets has a load factor of 25 / 50 = 0.5. If the table’s capacity increases to 100 buckets while the number of entries remains unchanged, its load factor becomes 25 / 100 = 0.25. Capacity describes available space, while load factor describes how densely that space is being used.
10. Does a Low Load Factor Always Mean a Hash Table Is Efficient?
No, a low load factor does not always guarantee efficient hash table operations. Although a low value usually means more available capacity, performance also depends on the hash function, key distribution, collision-resolution strategy, and implementation. For example, a poor hash function might map many different keys to the same bucket even when the table has many unused buckets. This can cause slow searches despite a low load factor. Additionally, maintaining excessive capacity may waste memory. To evaluate a hash table properly, developers should consider the load factor alongside collision behavior, memory consumption, and actual operation performance.