Algorithms are an essential part of computer science. They provide step-by-step instructions for solving problems, processing data, and performing calculations. However, not all algorithms solve the same problem with equal efficiency. Some complete their tasks almost instantly, while others require significantly more time or memory as the amount of input data increases.
Algorithm efficiency helps us understand how well an algorithm uses computational resources, especially execution time and memory. Growth rate formulas allow us to estimate how an algorithm’s resource requirements change when the input size becomes larger. These concepts are important when designing programs that can handle large amounts of data efficiently.
In this article, we will learn the basic formulas used to analyze algorithm efficiency, including constant, logarithmic, linear, linearithmic, quadratic, and exponential growth rates. We will also explore Big O notation, common complexity classes, and practical examples that make these formulas easier to understand.
What Is Algorithm Efficiency?
Algorithm efficiency refers to the amount of computational resources an algorithm requires to complete a task. The two main resources used to measure efficiency are time and space.
Time complexity describes how the number of operations performed by an algorithm grows as the input size increases. It does not usually measure the exact time in seconds because execution time depends on hardware, programming languages, and other factors.
Space complexity describes how much additional memory an algorithm requires as the input size grows. It may include temporary variables, data structures, and additional memory used during execution.
For example, suppose two algorithms search for a particular number in a list containing one million elements. One algorithm might examine each element individually, while another might repeatedly divide a sorted search range in half. Both can solve the same problem, but their efficiency can be very different.
Understanding algorithm efficiency helps programmers choose appropriate solutions for problems of different sizes.
What Is Input Size?
Input size is the amount of data an algorithm processes. It is commonly represented by the variable (n).
Depending on the problem, (n) may represent the number of elements in an array, the number of characters in a string, the number of nodes in a graph, or the number of records in a database.
For example, if an algorithm processes an array containing 100 elements, its input size is (n = 100). If the array contains 10,000 elements, the input size is (n = 10{,}000).
The number of operations performed by an algorithm often depends on this input size. Growth rate formulas describe how that number changes when (n) increases.
What Is a Growth Rate in Algorithm Analysis?
A growth rate describes how quickly an algorithm’s resource requirements increase as the input size becomes larger.
Some algorithms perform nearly the same amount of work regardless of input size. Others perform work proportional to the number of elements, while some require much more work as the input grows.
For example, an algorithm that performs approximately (n) operations has linear growth. If the input size doubles, the number of operations also approximately doubles.
An algorithm that performs approximately (n^2) operations has quadratic growth. If the input size doubles, the number of operations may increase by roughly four times.
Growth rates help us compare algorithms independently of specific computers or programming environments.
Basic Algorithm Efficiency and Growth Rate Formulas
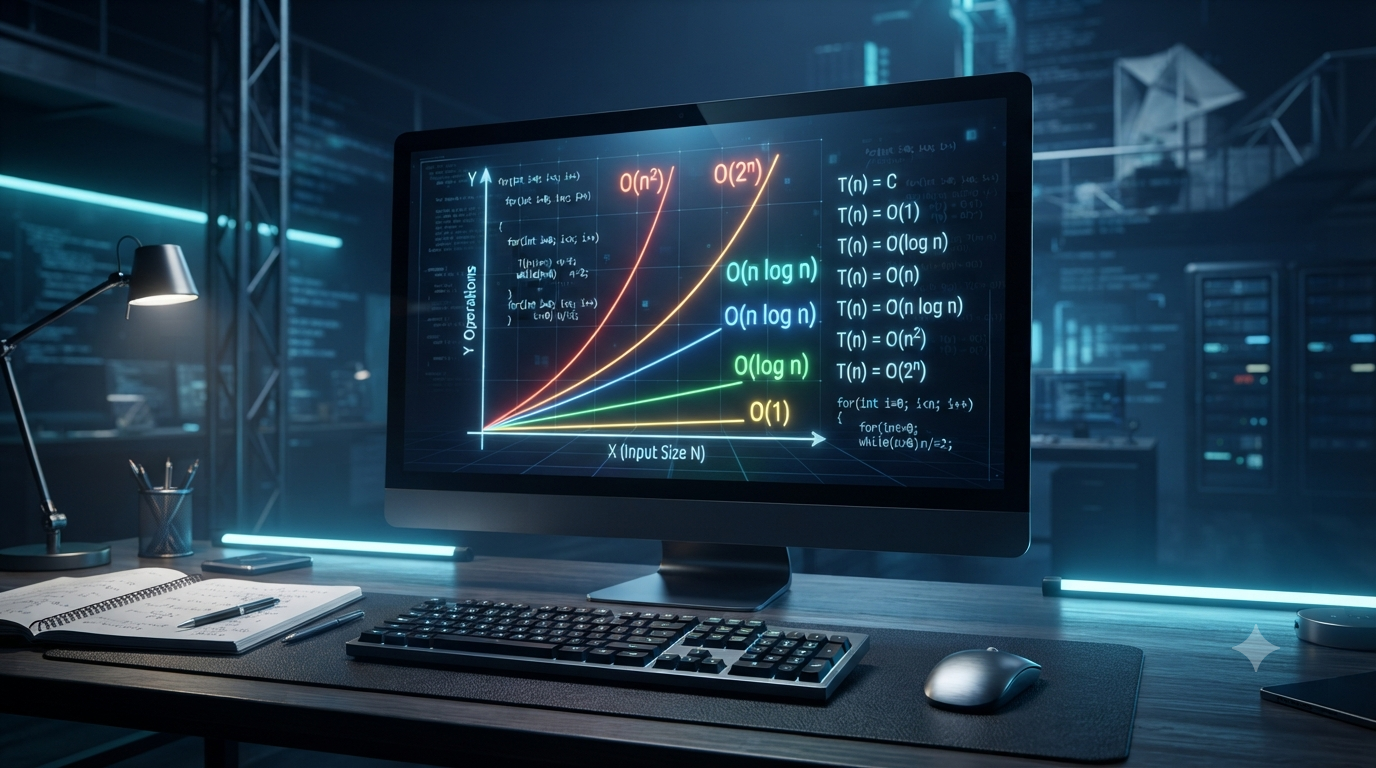
The following formulas represent some of the most common growth rates in computer science.
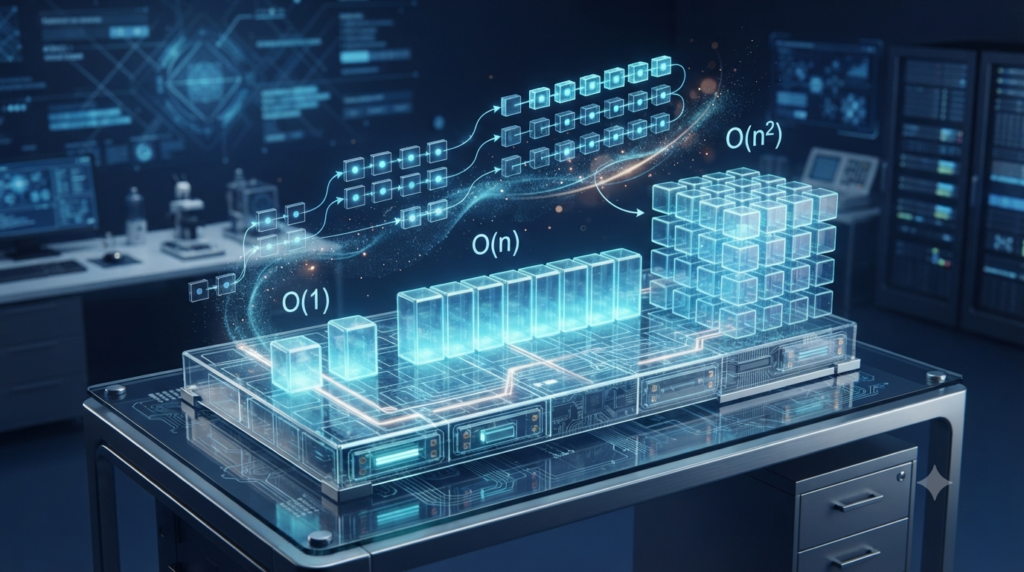
1. Constant Time Complexity — O(1)
Constant time complexity means that the number of operations remains approximately constant as the input size increases.
Formula:
(T(n) = c)
Big O notation: (O(1))
Here, (T(n)) represents the number of operations or the time required, and (c) is a constant.
For example, accessing an element in an array by its index usually takes constant time:
numbers = [10, 20, 30, 40, 50]
The program accesses the element at index 2 directly. The array’s size does not normally change the number of steps needed for this access.
Constant-time operations are generally highly efficient. However, an algorithm may contain other operations that make its overall complexity higher.
2. Logarithmic Time Complexity — O(log n)
Logarithmic time complexity occurs when an algorithm repeatedly reduces the problem size by a constant factor, often by half.
Formula:
(T(n) = \log_2 n)
Big O notation: (O(\log n))
A common example is binary search, which searches for a target value in a sorted array by examining the middle element and eliminating half of the remaining search range at each step.
Suppose a sorted array contains 1,024 elements. Binary search can reduce the search range to a single candidate in about 10 halving steps, since (2^{10} = 1{,}024).
If the array grows to 2,048 elements, the number of halving steps increases by only about one.
Logarithmic algorithms are especially useful when working with large datasets because their operation counts increase slowly as the input size grows.
3. Linear Time Complexity — O(n)
Linear time complexity means that the amount of work increases in proportion to the input size.
Formula:
(T(n) = cn)
Big O notation: (O(n))
Here, (c) represents the approximate amount of work performed for each input element.
For example, consider an algorithm that calculates the sum of all numbers in an array. It must examine every element at least once.
numbers = [10, 20, 30, 40, 50]
If the array contains 100 elements, the loop processes 100 elements. If it contains 1,000 elements, it processes 1,000 elements.
The number of operations increases approximately in proportion to (n), making this a linear-time algorithm.
Linear complexity is common in algorithms that scan arrays, count elements, or process every record in a dataset.
4. Linearithmic Time Complexity — O(n log n)
Linearithmic time complexity combines linear and logarithmic growth.
Formula:
(T(n) = cn\log_2 n)
Big O notation: (O(n\log n))
This growth rate commonly appears in efficient sorting algorithms, including merge sort and average-case heap sort.
Merge sort divides an array into smaller parts, sorts those parts, and combines them into a sorted result. The division process creates approximately (\log_2 n) levels, and processing across each level requires approximately (n) total work.
Therefore, its overall time complexity is (O(n\log n)).
For an input containing 1,000 elements, (n\log_2 n) is approximately 9,966. This value is a simplified growth estimate, not an exact count of the operations performed by every implementation.
Linearithmic algorithms are often suitable for large datasets because they generally scale much better than quadratic sorting algorithms.
5. Quadratic Time Complexity — O(n²)
Quadratic time complexity occurs when the amount of work grows approximately with the square of the input size.
Formula:
(T(n) = cn^2)
Big O notation: (O(n^2))
Quadratic complexity frequently occurs when an algorithm uses two nested loops, each of which processes approximately (n) elements.
For example:
numbers = [1, 2, 3, 4, 5]
The outer loop runs five times, and the inner loop runs five times for every outer-loop iteration. The total number of iterations is (5 \times 5 = 25).
If the input contains 100 elements, the nested loops perform 10,000 iterations. With 1,000 elements, they perform one million iterations.
Quadratic algorithms can be acceptable for small inputs but may become slow as the dataset grows. Simple implementations of bubble sort and selection sort commonly have quadratic time complexity.
6. Cubic Time Complexity — O(n³)
Cubic time complexity means that the amount of work increases approximately with the cube of the input size.
Formula:
(T(n) = cn^3)
Big O notation: (O(n^3))
This complexity can occur when an algorithm uses three nested loops, each processing approximately (n) elements.
For example, three nested loops over an array containing 10 elements may execute the innermost statement (10 \times 10 \times 10 = 1{,}000) times.
If the input size increases to 100 elements, the corresponding iteration count becomes (100^3 = 1{,}000{,}000).
Cubic algorithms can become expensive for large inputs. Some straightforward algorithms for matrix operations and problems involving every possible triple of elements exhibit cubic growth.
However, not every algorithm with three nested loops necessarily has cubic complexity. The number of iterations in each loop and the relationships between them must also be considered.
7. Exponential Time Complexity — O(2ⁿ)
Exponential time complexity occurs when the amount of work grows exponentially with the input size.
Formula:
(T(n) = c2^n)
Big O notation: (O(2^n))
Exponential growth appears in some brute-force algorithms that examine every possible combination of binary choices.
For example, a set containing (n) elements has (2^n) possible subsets. An algorithm that explicitly examines every subset may therefore require exponential work.
When (n = 10), there are (2^{10} = 1{,}024) possible subsets. When (n = 20), there are (2^{20} = 1{,}048{,}576) possible subsets.
Doubling the input size in this example increases the number of subsets from 1,024 to more than one million.
Exponential algorithms can become impractical even for moderately sized inputs. Techniques such as dynamic programming, pruning, and specialized algorithms may reduce the amount of work required for particular problems.
8. Factorial Time Complexity — O(n!)
Factorial time complexity grows according to the factorial of the input size.
Formula:
(T(n) = cn!)
Big O notation: (O(n!))
The factorial of a positive integer is the product of all positive integers up to that number.
For example:
(5! = 5 \times 4 \times 3 \times 2 \times 1 = 120)
Factorial growth often appears in brute-force algorithms that generate and examine every possible ordering of (n) distinct elements.
A collection of five distinct elements has (5! = 120) possible arrangements. A collection of ten elements has (10! = 3{,}628{,}800) arrangements.
As the input size increases, the number of possible arrangements grows extremely quickly. Consequently, factorial-time algorithms are generally practical only for small inputs unless additional techniques reduce the search space.
Comparison of Common Growth Rates
The following table summarizes the main growth rate formulas.
| Growth rate | Formula | Common example |
|---|---|---|
| Constant | (O(1)) | Array index access |
| Logarithmic | (O(\log n)) | Binary search |
| Linear | (O(n)) | Array traversal |
| Linearithmic | (O(n\log n)) | Merge sort |
| Quadratic | (O(n^2)) | Bubble sort |
| Cubic | (O(n^3)) | Some triple-loop algorithms |
| Exponential | (O(2^n)) | Subset enumeration |
| Factorial | (O(n!)) | Brute-force permutation generation |
These examples are typical patterns rather than universal rules. Actual complexity depends on the algorithm’s implementation, assumptions, and the input being processed.
What Is Big O Notation?
Big O notation is a mathematical way to describe an upper bound on how an algorithm’s resource requirements grow as the input size increases.
It focuses on the dominant growth behavior rather than exact operation counts. For example, an algorithm requiring approximately (3n^2 + 5n + 10) operations has a Big O time complexity of (O(n^2)).
The quadratic term dominates when (n) becomes sufficiently large. The lower-order terms and constant factors become less significant in the asymptotic analysis.
Big O notation makes it easier to compare algorithms without depending on a specific computer or programming language.
It is important to understand that Big O does not automatically describe the exact execution time or always represent the average case. Depending on the analysis, it may describe worst-case, average-case, or another specified behavior.
Other Important Asymptotic Notations
Although Big O is widely used, algorithm analysis includes other mathematical notations.
Big Omega — Ω
Big Omega notation describes an asymptotic lower bound on a function’s growth.
For example, if an algorithm must inspect every element in an unsorted array to calculate its sum, its running time is (\Omega(n)) under the usual unit-cost model.
Big Theta — Θ
Big Theta notation describes a tight asymptotic bound when the function grows at the same order as the stated comparison function.
For example, a simple loop that processes every element exactly once has time complexity (\Theta(n)), assuming each iteration performs constant work.
These notations describe different mathematical bounds. They should not be confused with best-case, average-case, and worst-case analysis, which describe different ways of evaluating an algorithm’s behavior.
How to Calculate Algorithm Time Complexity
You can estimate the time complexity of a basic algorithm by examining its operations and control structures.
Step 1: Identify the Input Size
Determine what (n) represents in the problem. It might be the number of array elements, characters, or records.
Step 2: Count the Main Operations
Identify the operations that contribute most to the algorithm’s running time. These might include comparisons, assignments, arithmetic calculations, or loop iterations.
Step 3: Analyze Loops
A single loop that processes (n) elements generally has (O(n)) time complexity.
Two independent consecutive loops that each process (n) elements require approximately (2n) iterations in total. Since constant factors are ignored in Big O notation, the overall complexity remains (O(n)).
Two nested loops that each process (n) elements generally produce (O(n^2)) complexity.
Step 4: Consider Repeated Division
If a loop repeatedly divides its input or search range by two, it may have logarithmic complexity, (O(\log n)).
Step 5: Keep the Dominant Term
Remove constant factors and lower-order terms when expressing the final Big O result.
For example:
(T(n) = 4n^2 + 3n + 12)
The dominant term is (n^2), so the Big O complexity is (O(n^2)).
Time Complexity vs Space Complexity
Time complexity and space complexity measure different resources.
Time complexity estimates how the amount of computational work grows with the input size. Space complexity estimates how the memory requirement grows.
For example, an algorithm that scans an array to find its largest element can operate in (O(n)) time while using (O(1)) auxiliary space. It examines each element but only needs a few additional variables.
Another algorithm might copy the entire array before processing it. The additional memory required for that copy grows linearly, producing (O(n)) auxiliary space.
The most efficient solution is not necessarily the one with the lowest time complexity alone. In practical applications, programmers may need to balance execution time, memory use, readability, and implementation complexity.
Why Growth Rate Formulas Matter
Growth rate formulas help programmers understand how algorithms behave as applications process larger amounts of information.
For small inputs, two algorithms with different complexities may both run quickly. As the input grows, however, their performance can differ substantially.
For example, a quadratic algorithm may be entirely adequate for a list of 20 elements but become inefficient for a list containing 100,000 elements. A more efficient algorithm may require additional implementation effort but save substantial computation as the dataset grows.
Growth rate analysis is useful in database systems, search engines, artificial intelligence, scientific computing, data analysis, and many other areas of computer science.
It also helps developers recognize when a problem requires a more efficient algorithm, an improved data structure, or a different computational approach.
Conclusion
Basic algorithm efficiency and growth rate formulas provide a foundation for understanding how computer programs perform as their input sizes increase. Time complexity measures computational work, while space complexity measures memory requirements. Common growth rates include constant (O(1)), logarithmic (O(\log n)), linear (O(n)), linearithmic (O(n\log n)), quadratic (O(n^2)), cubic (O(n^3)), exponential (O(2^n)), and factorial (O(n!)).
Big O notation helps describe an algorithm’s asymptotic upper bound, while Big Omega and Big Theta provide lower-bound and tight-bound descriptions. By learning to recognize common growth patterns, analyze loops, and identify dominant terms, beginners can compare algorithms and make better programming decisions. These concepts form an important foundation for studying data structures, sorting, searching, and advanced algorithm design.
FAQs
1. What Is Algorithm Efficiency in Computer Science?
Algorithm efficiency describes how effectively an algorithm uses computational resources to solve a problem. The two primary measures are time complexity and space complexity. Time complexity explains how the number of operations grows as the input size increases, while space complexity describes how memory requirements change. For example, an algorithm that searches a sorted array using binary search is generally more efficient for large datasets than a simple linear search. Understanding algorithm efficiency helps programmers select suitable algorithms, improve application performance, reduce resource consumption, and build software that can handle increasing amounts of data.
2. What Are Algorithm Growth Rate Formulas?
Algorithm growth rate formulas describe how an algorithm’s computational requirements change as its input size increases. Common formulas include 1, log₂ n, n, n log₂ n, n², n³, 2ⁿ, and n!. These expressions represent constant, logarithmic, linear, linearithmic, quadratic, cubic, exponential, and factorial growth, respectively. For example, a linear algorithm performs work proportional to the input size, whereas a quadratic algorithm may perform work proportional to its square. Learning these formulas helps programmers compare algorithms, predict scalability, and identify solutions that remain practical when processing larger datasets.
3. What Is Big O Notation in Algorithm Analysis?
Big O notation describes an asymptotic upper bound on how an algorithm’s resource requirements grow as the input size increases. It focuses on growth behavior rather than exact execution time. For example, an algorithm requiring approximately 5n + 10 operations has O(n) time complexity because its dominant growth is linear. Similarly, an algorithm requiring 3n² + 4n + 8 operations has O(n²) complexity. Big O notation allows programmers to compare algorithms without depending on specific hardware or programming languages. However, it does not automatically indicate exact running time or always describe average-case performance.
4. What Is the Difference Between O(1), O(n), and O(n²)?
O(1), O(n), and O(n²) represent three different growth rates. Constant complexity, O(1), means the amount of work remains approximately unchanged as the input grows. Linear complexity, O(n), means the work increases proportionally with the input size. Quadratic complexity, O(n²), means the work can increase proportionally to the square of the input size. For example, accessing an array element by index is typically O(1), examining every element is O(n), and comparing every pair of elements using nested loops is often O(n²). These differences become increasingly important when algorithms process large datasets.
5. What Is the Difference Between Time Complexity and Space Complexity?
Time complexity measures how an algorithm’s computational work grows with the input size, whereas space complexity measures how its memory requirements grow. An algorithm may process every element in an array once, resulting in O(n) time complexity, while using only a fixed number of additional variables, resulting in O(1) auxiliary space complexity. Another algorithm might create a separate copy of the entire array, requiring O(n) additional memory. Both measurements are important when evaluating software. An algorithm with excellent execution speed may consume too much memory, while a memory-efficient solution may require more processing time.
6. Why Is O(log n) More Efficient Than O(n)?
O(log n) generally grows more slowly than O(n) as the input size becomes large. In a logarithmic algorithm, the problem size is repeatedly reduced by a constant factor, often by half. Binary search demonstrates this principle by eliminating half of a sorted search range after each comparison. For an array containing 1,024 elements, approximately 10 halving steps are sufficient to narrow the range to one candidate. A linear search might examine as many as 1,024 elements. Therefore, logarithmic algorithms can offer substantial performance advantages for large inputs, provided the problem and data structure support their use.
7. What Is the Difference Between O(n log n) and O(n²)?
O(n log n) grows more slowly than O(n²) as the input size becomes large. Linearithmic complexity commonly appears in efficient sorting algorithms such as merge sort, while quadratic complexity appears in simple implementations of bubble sort and selection sort. For example, when processing 1,000 elements, n² equals 1,000,000, whereas n log₂ n is approximately 9,966. These figures illustrate the difference in growth rates rather than exact operation counts. Although both algorithms may perform adequately on small inputs, an O(n log n) algorithm generally scales better when sorting large collections of data.
8. What Are Exponential and Factorial Time Complexities?
Exponential complexity, commonly represented by O(2ⁿ), occurs when computational work doubles with each additional input element in a typical exponential-growth model. Factorial complexity, O(n!), appears in algorithms that examine every possible ordering of distinct elements. For example, a set containing 10 elements has 2¹⁰, or 1,024, possible subsets, while 10 distinct elements have 10!, or 3,628,800, possible arrangements. Both growth rates increase extremely quickly, making straightforward algorithms with these complexities impractical for many large inputs. Optimization techniques, pruning, and specialized algorithms can sometimes reduce the amount of work required.
9. How Do You Calculate the Time Complexity of an Algorithm?
To calculate time complexity, first identify the input size, usually represented by n. Next, examine the algorithm’s operations and determine how their number changes as n increases. A single loop processing every element generally has O(n) complexity. Two nested loops that each process n elements typically have O(n²) complexity. Repeatedly halving a search range often produces O(log n) complexity. Finally, simplify the expression by removing constant factors and lower-order terms. For example, 4n² + 3n + 10 becomes O(n²). This method provides a useful estimate of an algorithm’s growth behavior.
10. Why Are Algorithm Efficiency Formulas Important for Programmers?
Algorithm efficiency formulas help programmers choose solutions that remain practical as applications grow. A program that performs well with a small dataset may become slow when handling thousands or millions of records. Understanding growth rates allows developers to identify potential performance problems before they become serious. These concepts are useful in database processing, search systems, artificial intelligence, scientific computing, and software development. They also provide a foundation for studying data structures, sorting algorithms, graph algorithms, and optimization techniques. By understanding time and space complexity, programmers can make informed decisions about execution speed, memory usage, scalability, and overall software performance.